Mobile product leaders no longer need convincing that AI matters in the build process. The practical question is where it shortens the path to a reliable product and where it quietly adds work that was not previously there. The answer varies more than general industry framing suggests, and it depends on the task, the stack, and the team.
A short scope note: this article is about using AI to help build a mobile app, not about adding AI features inside the app for users. Both are legitimate decisions, but they carry different tradeoffs and are often conflated in strategy conversations. The rest of the piece stays with the first.
Where AI Helps in Mobile Development Today
Several parts of the mobile workflow have changed with capable AI assistance in the loop, though the size and consistency of the benefit vary by task and reviewer. The honest framing is “sometimes meaningful, often situational,” not “uniformly transformative.”
Prototyping tools that integrate large language models can produce layout variations, flow drafts, or component scaffolding more quickly than purely manual methods. Whether this translates into shipping better products depends on how disciplined the team is about testing those prototypes with real users. The acceleration is in production time, not in the judgment about what to build.
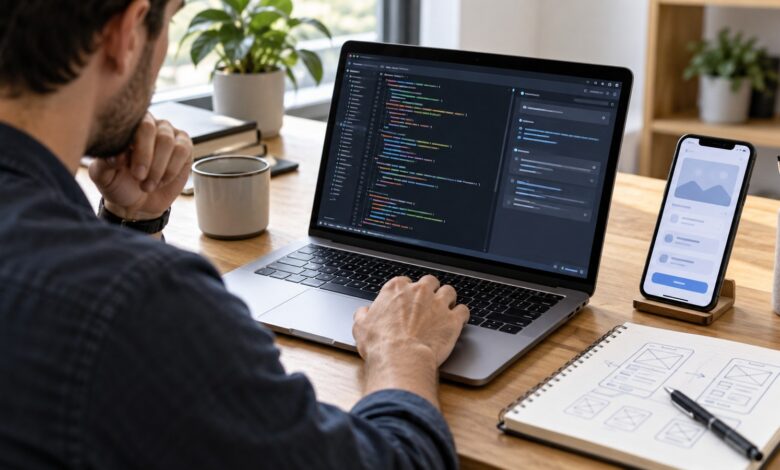
Coding assistance is the most visible change. Tools built on large language models can draft boilerplate, suggest completions, scaffold common patterns, generate test cases, and rewrite short sections of code. The benefit tends to be most consistent on routine tasks in well-trodden stacks, and less consistent on novel work or less familiar codebases.
Documentation and internal tooling can benefit when a team already values them. Drafting API docs, inline comments, release notes, or runbooks is often faster when a first draft can be edited rather than written from scratch. Teams that previously skipped documentation do not reliably start maintaining it just because the per-page cost has dropped.
The Verification Tax
Producing code faster is not the same as delivering a reliable product faster. The research available in 2026 supports a cautious reading rather than a definitive one in either direction.
A controlled 2025 study by METR, run with experienced open-source contributors working on repositories they knew well, found that participants were about nineteen percent slower on real tasks when using early-2025 AI tools, even when they expected to be faster. The study was narrow in scope and presented as a specific observation about that population and those tools, not a general verdict. METR’s February 2026 update reported that later evidence suggested improved productivity in some settings, while noting that selection and measurement problems prevented a reliable estimate across different populations and tasks.
Taken together, these findings do not generalize cleanly to 2026 tools or to teams working in different contexts. The slowdown in the earlier study was not attributable to any single cause and should not be reduced to “review overhead” alone. For well-scoped work on familiar territory, modern tools often help; for other work, the net effect is less clear, and teams that measure total task time and defect rates against their own baselines are best positioned to decide where to lean on AI.
Several factors shape that net result. AI-generated code can be subtly wrong in ways that compile cleanly and pass visual review but fail at runtime. Integration time, context-switching, and reviewer vigilance all consume time that is easy to miss when only “lines produced” is measured.
A Hypothetical Mobile Example
Consider a two-person iOS team adding a new in-app purchase flow to an existing paid app. The engineer uses AI assistance to scaffold StoreKit code, generate initial unit tests, and draft the privacy disclosure for the App Store listing. The raw generation takes a few hours instead of a day.
Review takes longer than expected. The scaffolded code uses an older StoreKit pattern that compiles but is deprecated for new work. The generated tests pass but miss two important edge cases around receipt validation. The reviewer rewrites one test from scratch, replaces the deprecated pattern, and checks the disclosure against current App Store policy before submitting.
The net saving in this illustration is modest, measured honestly, and heavily dependent on the reviewer’s familiarity with StoreKit. It is not zero, and in many teams it is a real win. It is also not the dramatic acceleration that generic productivity narratives often imply.
Where Human Judgment Still Owns the Outcome
Several areas of mobile product work remain fundamentally judgment-driven. Problem validation is the first. Deciding whether an app should exist, who it is for, and what the smallest version needs to prove depends on talking to real people and interpreting ambiguous signals.
Product prioritization has the same character. Weighing user needs, business constraints, technical risk, and strategic bets carries accountability that does not transfer to a tool. The decision about what ships in a first release still belongs to the team.
Architecture, security, and privacy decisions sit in the same category. Choosing a backend architecture, designing authentication, deciding what data leaves the device, and planning for GDPR or CCPA compliance require human responsibility and often legal review. The OWASP Mobile Application Security project provides the Mobile Application Security Verification Standard (MASVS) for defining security requirements and the Mobile Application Security Testing Guide (MASTG) for testing against them, both of which are useful references for mobile threat modeling. The NIST AI Risk Management Framework provides adjacent guidance that reinforces the need for human oversight of security-relevant AI-assisted work.
Accessibility is often oversold as an AI-automatable area. Automated tooling catches a share of issues but misses many that affect real users, a point the W3C’s web accessibility guidance has made for years in the context of websites. Native mobile apps have their own platform-specific accessibility requirements through Apple’s and Google’s APIs, and shipping an accessible mobile app still requires informed design and testing with people who use assistive technology.
Quality assurance follows the same logic. AI-generated tests can expand coverage quickly, but a suite that passes without exercising behaviors users care about creates false confidence. Someone still has to decide what should be tested, how, and when a release is acceptable.
Maintenance is the quietest of these and often matters most over time. Apple’s App Store Review Guidelines continue to evolve, and Google Play’s target API level requirements require live apps to keep pace or lose discoverability for new users. Keeping an app in good standing through these changes is sustained human work.
What to Actually Do With This
A practical approach for product leaders in 2026 is to be specific about delegation and verification rather than treating AI as a general productivity setting.
Delegate to AI tasks where the correct answer is reasonably checkable and the cost of a small error is contained. Boilerplate, format transformations, first-draft unit tests, documentation drafts, and layout variations are reasonable candidates. Keep humans accountable for problem definition, prioritization, architecture, security and privacy, accessibility, QA strategy, release decisions, and anything with legal or regulatory weight. These are the areas where responsibility does not transfer and where overreliance on generated output produces the most expensive mistakes.
Measure outcomes, not keystrokes. Track total task time including review and rework, not raw generation speed. Watch post-release defect rates, crash reports, and support volume after features that relied heavily on AI assistance, and compare them to baselines from similar work done without those tools. If the overall picture improves, lean in further; if it does not, pull back on the tasks where the tool is not earning its place.
The useful question in 2026 is not “is AI transforming development?” It is “which specific tasks, in our specific context, measurably benefit, and which do not?” Teams that can answer that honestly tend to extract more value from AI than teams that treat it as a general multiplier.