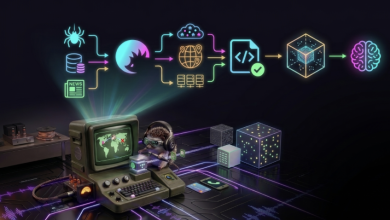
AI is changing DevOps work fastest where teams already have repeatable pipelines, clear ownership, and enough operational data to learn from. It can help summarize incidents, detect noisy deployment patterns, suggest infrastructure changes, review configuration drift, and speed up routine scripting. But it cannot fix a weak release process by itself. When CI/CD is fragile, observability is thin, and nobody agrees who owns production, adding AI usually gives the team faster confusion instead of better delivery.
For developers, the real question is no longer whether AI belongs somewhere in DevOps. It is where it can safely help, where it should stay supervised, and where human engineers still need to make the final call.
Where AI fits into DevOps development
Most teams do not need AI scattered everywhere. They need it placed in boring but expensive parts of the workflow: log analysis, pipeline diagnostics, test failure grouping, infrastructure review, alert triage, and documentation updates. These are places where engineers lose hours reading repetitive output, chasing old errors, or explaining the same incident pattern again.
Teams comparing AI DevOps Development Services are usually dealing with that exact problem. They are not trying to replace DevOps engineers. They are trying to build delivery systems where automation, cloud infrastructure, monitoring, and human review work together without turning every release into a manual rescue mission.
A useful AI-assisted DevOps setup should answer practical questions faster:
- Why did this deployment fail?
- Which tests are flaky and which are real blockers?
- What changed in infrastructure since the last stable release?
- Which alerts are symptoms, and which one points to the actual fault?
- What should be checked before rollback?
AI should read the pipeline before it writes changes
The riskiest DevOps mistake is giving an AI tool write access before the team understands what it is reading. A model can generate Terraform, Kubernetes manifests, GitHub Actions workflows, Dockerfiles, or monitoring rules very quickly. That speed is useful only when the output goes through review, testing, policy checks, and version control.
A safer pattern is read first, suggest second, change third.
- AI reviews logs, metrics, pipeline output, and recent commits.
- It summarizes possible causes and affected services.
- Engineers check the reasoning against the dashboards and code.
- The tool suggests a patch, configuration change, or rollback path.
- The change passes tests, policy checks, and human approval before merge.
CI/CD is the first place to clean up
AI performs better when the pipeline is already understandable. If builds fail for random reasons, test names are unclear, artifacts are not traceable, and deployment logs are inconsistent, AI has less useful context. It may still produce a confident answer, but confidence is not the same as correctness.
Before adding AI into CI/CD, teams should clean up the basics:
| Pipeline area | What to fix before adding AI |
| Build logs | Consistent formatting and clear failure messages |
| Tests | Separate flaky tests from release-blocking failures |
| Deployments | Trace each release to commit, artifact, and environment |
| Secrets | Remove sensitive data from logs and prompts |
| Rollbacks | Document when to roll back and who approves it |
| Monitoring | Connect deploy events with metrics and alerts |
Infrastructure as code still needs engineering judgment
Infrastructure as code is one of the most tempting areas for AI-assisted DevOps. The tool can draft modules, spot repeated patterns, suggest variable names, and explain why a resource may not match the expected environment. That is helpful, especially when a team is working across AWS, Azure, Kubernetes, Terraform, Helm, or several internal templates.
The danger appears when generated infrastructure looks valid but does not fit the organization’s real constraints. A config may pass syntax checks while opening access too widely, using the wrong region, ignoring cost limits, or breaking naming rules that other systems depend on.
A safer review routine for AI-generated infrastructure
Before merging AI-assisted infrastructure changes, engineers should check:
- access permissions and identity boundaries
- network exposure and ingress rules
- region, environment, and naming conventions
- cost impact of new resources
- state file behavior and drift risk
- rollback path if the change fails
- policy-as-code results
- monitoring and alert coverage after deployment
Observability is where AI becomes more useful
Observability is often where AI provides the most immediate value. Logs, traces, metrics, and deployment events create more information than humans can comfortably scan during an incident. AI can group related alerts, summarize timeline changes, compare current behavior with previous deployments, and point engineers toward the service that changed before the failure began.
The best use is not magic root-cause analysis. It is faster orientation.
During an incident, an AI assistant might produce a short timeline:
- deployment started at 14:05
- error rate increased at 14:08
- latency rose only on checkout endpoints
- database connections stayed stable
- cache misses increased after the new release
- rollback reduced errors within six minutes
Security cannot be added after automation
AI-assisted DevOps needs security rules from the start. A model should not receive secrets, raw customer data, private keys, tokens, or sensitive production logs without clear controls. Teams also need to decide which outputs can be trusted automatically and which require manual approval.
Good DevOps automation uses layers: secret scanning, dependency checks, image scanning, policy-as-code, access reviews, audit logs, and protected branches. AI should work inside those layers, not beside them.
The most practical security rule is simple: never allow an AI-generated change to bypass the same checks a human change must pass. If the team would reject a developer pushing directly to production, it should reject AI doing the same thing faster.
Better DevOps still depends on people
AI can reduce repetitive work, shorten incident analysis, and make pipeline feedback easier to read. It can help a developer understand a failed build faster or help an operations engineer compare infrastructure drift across environments. Those gains matter when teams ship often and support production every day.
But DevOps remains a people-and-process discipline. The strongest systems still depend on clear ownership, small releases, readable alerts, documented recovery paths, and engineers who know when automation is wrong. AI works best when it supports those habits.
A healthy AI DevOps setup should leave the team with fewer blind spots, fewer repetitive checks, and faster recovery from routine failures. It should not create a black box that nobody trusts. The goal is a delivery process where AI helps engineers move sooner, but humans still decide what reaches production.