Everyone is watching the models. Larger context windows, more capable agents, cheaper inference and increasingly sophisticated reasoning dominate the AI conversation.
The real enterprise AI battle is happening somewhere less visible: underneath the model.
AI systems cannot reason reliably over information they cannot find, trust or access at the right moment. Enterprises are discovering that fragmented data, inconsistent permissions, stale retrieval pipelines and weak observability can neutralise even the strongest models. Bapi Raju Ipperla’s broader work on AI-ready data platforms centres on this same principle: enterprise AI becomes a data engineering problem before it becomes a model problem.
The stakes have shifted from deploying AI tools to building an operating foundation that can support intelligence at scale.
The Burning Platform: AI Adoption Is Outrunning AI Infrastructure
AI adoption is no longer the constraint. Production readiness is.
The Adoption Gap. McKinsey’s 2025 research found that 88% of organisations were using AI in at least one business function. Yet only about one-third had begun scaling AI programmes across their enterprises. A separate McKinsey analysis reported that just 7% had fully scaled AI organisation-wide. (McKinsey & Company)
The Failure Gap. Gartner reported in January 2026 that at least 50% of generative AI projects had been abandoned after proof of concept by the end of the previous year. Poor data quality, inadequate risk controls, escalating costs and unclear business value were among the primary causes. (Gartner)
The Agentic Pressure. The infrastructure problem becomes harder as enterprises move from assistants that answer questions to agents that take actions. Gartner predicts that more than 40% of agentic AI projects will be cancelled by the end of 2027 because of costs, unclear value or inadequate controls. (Gartner)
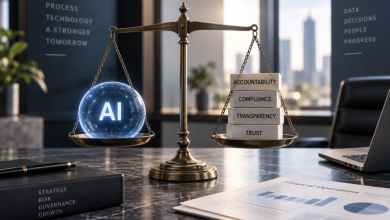
The bottom line: enterprises do not have an AI access problem anymore. They have an AI readiness problem.
The New Playbook: Build Intelligence From the Platform Up
- The Context Architect: Give AI the Right Data, Not More Data
The obsession with context-window size misses the enterprise problem. A model with a massive context window still fails if the information entering that window is outdated, contradictory or improperly authorised.
Enterprises need a governed context layer connecting transactional systems, operational databases, documents, event streams and knowledge stores. The objective is not to expose everything. It is to provide the minimum accurate context required for each decision.
Context is becoming infrastructure.
- The Real-Time Engineer: Replace Yesterday’s Data With Now
Traditional analytics platforms were built around human decision cycles. An overnight batch process was acceptable when the result became tomorrow morning’s dashboard.
AI agents operate differently. Fraud detection, recommendations, customer support, operational automation and personalised decisions can depend on events that occurred seconds earlier.
That makes streaming architecture strategically important. Events need to move from operational systems into usable AI context continuously, with mechanisms for deduplication, ordering, schema evolution and failure recovery.
The difference between intelligent automation and confidently wrong automation can be a few minutes of data latency.
- The Governance Architect: Put Permissions Below the Model
One of the most dangerous shortcuts in enterprise AI is allowing every application team to build its own data-access controls.
That approach does not scale.
Permissions, consent, masking, regional restrictions and access policies should be enforced by the underlying data and API layers before information reaches the model. An AI application should receive only what the requesting user and workflow are permitted to see.
Everyone forgets the counterintuitive part: better AI governance often requires less AI logic. The strongest control is preventing inappropriate information from entering the model in the first place.
- The Retrieval Engineer: Treat RAG as a Data Pipeline
Retrieval-augmented generation is frequently described as an AI architecture. In production, much of the difficult work is data engineering.
Documents change. Permissions change. Products change. Policies expire. Customer information evolves.
A retrieval system therefore needs ingestion, metadata management, synchronisation, access control, indexing, lineage and freshness monitoring. If those components fail, better embeddings cannot rescue the answer.
RAG is not simply model plus vector search. It is a continuously maintained knowledge supply chain.
- The Observability Engineer: Trace the Answer Backwards
Traditional systems ask whether a service is available.
AI systems force a harder question: why did the system produce this particular answer?
Production AI needs visibility across model calls, retrieved information, APIs, transformations, permissions and source freshness. When an answer is incorrect, teams must distinguish between a reasoning failure and an upstream data failure.
That distinction matters because the remedy is completely different.
AI observability therefore has to extend beyond latency and compute utilisation. Enterprises need the ability to trace intelligence back to its evidence.
Case Studies in the Wild: Infrastructure Wins Quietly
Uber: Real-Time Infrastructure at Operational Scale. Uber has extensively documented the event-driven and streaming architectures supporting real-time marketplace decisions across its platform. The crucial lesson is not that every company needs Uber’s architecture. It is that intelligent decision-making becomes more valuable as the delay between an event and the system’s understanding of that event approaches zero.
Netflix: Build Platforms, Not One-Off Pipelines. Netflix has long treated data infrastructure as a reusable internal platform supporting analytics, experimentation and personalisation rather than creating isolated pipelines for every use case. The crucial lesson is architectural leverage: every new intelligent capability becomes easier when common foundations already exist.
LinkedIn: Data Movement as Infrastructure. LinkedIn’s development of large-scale event-streaming infrastructure demonstrated how continuous data movement can become a foundational enterprise capability rather than a feature-specific integration. The lesson applies directly to AI: real-time intelligence requires reliable movement of context before any model can reason over it.
The pattern is consistent. Strong AI applications are rarely isolated technical achievements. They sit on reusable systems that make trusted information available repeatedly.
The Action Plan: Build an AI-Ready Foundation in 90 Days
Days 0-15: Map the Data Reality. Identify the first three high-value AI workflows. Trace every data source each workflow requires. Document ownership, freshness, access controls and known quality problems.
Do not begin with models. Begin with dependencies.
Days 16-45: Build the Context Layer. Standardise interfaces for accessing core data. Introduce streaming where freshness materially affects decisions. Establish identity, permission and governance rules at the platform level instead of duplicating them inside applications.
Create one reusable path from enterprise data to AI.
Days 46-90: Prove Trust Before Scale. Deploy one production workflow with end-to-end observability. Measure retrieval quality, latency, data freshness, failure rates and business outcomes. Trace errors to their source and harden the platform before adding more use cases.
Pilots prove possibility. Platforms prove repeatability.
The Inevitable Future: Data Infrastructure Becomes AI Infrastructure
The model layer will keep changing.
Today’s strongest models will be replaced. Retrieval methods will improve. Agent architectures will evolve. Inference costs will decline, and organisations will move between model providers as economics and capabilities change.
The durable competitive asset sits below that volatility.
Enterprises that establish governed data access, real-time information movement, reliable retrieval, reusable APIs and end-to-end observability will be able to adopt new AI capabilities without rebuilding their foundations every year.
This is why the AI infrastructure conversation needs to move beyond GPUs and models. The deeper transformation is wiring intelligence into the data heart of the enterprise.
AI is becoming another consumer of enterprise infrastructure, but eventually the distinction between “AI infrastructure” and “data infrastructure” will disappear. The platform itself will become intelligent.
In enterprise AI, the most valuable asset is not the smartest model. It is the trusted context that makes the model useful.