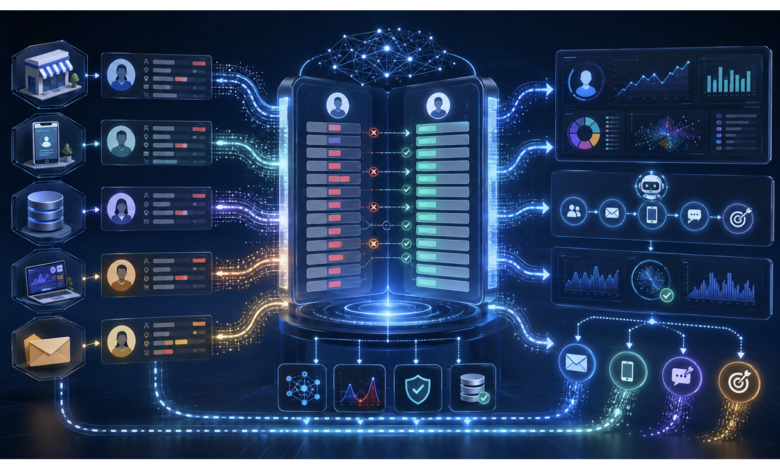
Lessons from designing a reconciliation system that compares customer attributes with their source of truth and feeds a separate correction job.
Consider a campaign assistant that checks an audience against a customer profile and approves it. The targeting logic is sound. The profile is well formed. But one of the attributes used to determine eligibility is an old value that the engagement platform never updated.
The assistant has evaluated the wrong state correctly.
This hypothetical example illustrates a problem I have worked on as a senior data engineer: customer data can disagree across systems even when individual pipelines report success. Adding an AI decision layer does not resolve that disagreement. It creates another consumer of it.
I designed a field-level reconciliation system between a central customer-data platform and a downstream marketing vendor. The reconciliation work identifies differences between corresponding customer attributes. A separate job compares against the source of truth and pushes corrections into the downstream system. The vendor and internal systems are unnamed here so the focus stays on the architecture.
This was data engineering work, not an AI model that decided which customer values were true. Its relevance to marketing AI is the control it provides over the evidence an automated system might use. The AI applications discussed below are design implications, not claims about agents deployed in this project.
A Successful Sync Does Not Prove the Systems Agree
A delivery pipeline and a reconciliation process answer different questions. One asks whether an update moved through the expected path. The other asks whether the destination now represents the intended customer state.
That distinction matters because divergence has several causes. A mapping can omit a field. A retry can replay an older update. A schema change can alter the meaning of a null. A downstream copy can lag behind the source. The reconciliation logic can also contain defects of its own.
Checking row counts, required fields, or job completion remains useful. But two datasets can pass those checks while disagreeing about a particular customer’s membership status or eligibility. A valid value in the wrong profile version is still a problem for the next decision.
In my work, the useful question was therefore more specific than whether the pipeline was healthy: which governed fields disagreed with their authoritative source, and what needed to happen to resolve that disagreement?
Define What a Match Means Before Comparing Values
Field-level reconciliation starts with a contract, not an equality operator.
For each attribute, the contract needs an authoritative source, an identity mapping, a transformation rule, and a freshness expectation. The downstream representation may legitimately differ from the source representation. Comparing raw values without accounting for that transformation can manufacture discrepancies.
Null handling deserves particular attention. A missing attribute, an explicit null, an empty string, and a default value may have different meanings. Treating all four as equivalent can hide a missed update; treating all four as different can generate unnecessary repairs. The rule must follow the field’s semantics.
The same applies to identifiers. Before comparing attributes, the system must establish that it has matched the same entity in both datasets. Duplicate or ambiguous identities should be surfaced separately rather than silently selecting a convenient record.
Here is an illustrative contract for a hypothetical eligibility field. It is not production configuration:
field: offer_eligible
authority: customer platform
comparison: normalized boolean
missing value: unresolved, not equivalent to false
freshness: both observations must meet the field’s policy
repair: allowed only after authoritative state is checked
This makes the ownership decision explicit. A downstream enrichment owned by the vendor would need a different rule and should not be overwritten merely because it differs from the central platform.
Separate Finding a Difference From Applying a Repair
The architecture I worked on separates reconciliation from the job that pushes corrections. That distinction is important: a discrepancy record is evidence for a repair decision, not an instruction that should be replayed indefinitely.
The high-level flow is:
Authoritative customer data + observed downstream state
-> field-level reconciliation
-> discrepancy records
-> separate job compares against the source of truth
-> corrections pushed to the downstream system
The separate job closes the operational loop. It turns reconciliation into a path for correcting downstream attributes rather than leaving every mismatch as a manual investigation.
There are still limits. A correction attempt does not prove that the destination applied the intended value. A successful request can be followed by delayed processing, another writer, or a mapping problem. For that reason, I would treat post-write verification as part of a complete control loop: observe the downstream value again and distinguish attempted, acknowledged, and verified repairs.
The safeguards below are design requirements I would apply to this pattern. They should not be read as a claim that every safeguard was implemented in this project.
The Repair Must Not Be Older Than the Data It Replaces
Consider a source snapshot captured at 10:00. A customer changes an attribute at 10:05, and the destination receives that update. At 10:10, a repair job compares the destination with the 10:00 snapshot and writes the older value back.
The two systems may now appear more consistent with the snapshot, but the customer state has become less correct.
This is why naming a source of truth is not sufficient. The correction job also needs to establish that the version it is using is appropriate for the write. Where available, source versions, per-record update times, or change events can help identify newer state. A timestamp alone is not a reliable ordering mechanism unless the clocks and timestamp semantics are understood.
Re-reading the source before repair reduces stale decisions but does not eliminate the race between reading and writing. Conditional updates or an ordered write path can provide stronger protection where the systems support them. If that protection is unavailable, the design needs a bounded repair policy, post-write reconciliation, and an explicit account of the remaining risk.
The job should also limit itself to fields it owns, tolerate safe retries, respect destination rate limits, and stop when discrepancy volume changes unexpectedly. A mapping bug that affects a large population should trigger investigation before it becomes a large automated overwrite.
For consent-sensitive attributes, an old snapshot must never be treated as permission to restore a previous subscription state. Reconciliation supplements the authoritative preference controls; it does not replace them.
Give AI a Reconciliation Status, Not a Blanket Guarantee
The next step for an AI-enabled workflow is to make data uncertainty usable by the decision system. A campaign assistant needs more than a profile value. It needs to know whether the relevant fields were checked, how recent the observations were, and whether discrepancies remain unresolved.
For example, an application could attach a compact status to the fields used in a decision:
checked_fields: [offer_eligible, membership_status]
comparison_status: unresolved
source_observed_at: <timestamp>
destination_observed_at: <timestamp>
policy_version: <version>
This is a proposed interface, not an existing project output. Its purpose is to let application policy decide what happens next. An unresolved high-impact field might require a fresh authoritative read, human review, or a hold on the affected action. A low-risk reporting task might proceed with an explicit freshness warning.
Those controls belong outside the model’s discretion. A prompt asking an agent to be careful is weaker than an application refusing to execute an action when a required data check has expired.
Reconciliation also has a clear boundary: agreement is not proof of truth. Both copies can contain the same upstream error. An AI system still needs source validation, authorization checks, model evaluation, and controls on the actions it can take. Reconciliation addresses cross-system disagreement within its defined coverage.
Measure Coverage and Resolution, Not Just a Green Job
A reconciliation job can complete successfully while inspecting only a small share of the fields that matter. It can also report few mismatches because one side of the comparison is missing.
I would measure the system along four dimensions:
- Coverage: the share of in-scope entity-field pairs actually checked, with missing or ambiguous records reported separately.
- Freshness: the age of the source and downstream observations relative to each field’s policy.
- Unresolved discrepancies: mismatches outside the allowed propagation window, measured against comparable pairs rather than all rows.
- Repair effectiveness: time to verified resolution, failed or skipped corrections, and discrepancies that recur after repair.
These measures should be broken down by field and business consequence. A low average mismatch rate can hide a problem concentrated in a critical eligibility attribute.
Preserving comparison history helps explain those patterns. An audit record should capture the field, observation times or versions, comparison-policy version, repair outcome, and a restricted reference to the affected entity. Store raw customer values only where needed, with appropriate access and retention limits.
A periodic comparison establishes when a mismatch was observed. It does not necessarily establish the exact moment the divergence began. Likewise, investigating an AI decision requires recording which input version the decision actually used, not merely looking at the latest reconciled profile.
Start With the Fields That Can Change an Action
For leaders planning this work, I would use a staged rollout rather than promise a fixed implementation timeline.
First, identify a small set of attributes whose disagreement changes an operational decision. Assign field owners and agree on identity, mapping, freshness, and repair rules. Run the comparison without writes so the team can examine false positives and expected propagation delays.
Next, enable correction for a limited set of deterministic cases. Bound the volume, monitor the destination, and verify the resulting state. Keep ambiguous ownership, identity conflicts, and unexpected changes in a review path.
Finally, connect reconciliation status to the applications that consume those fields. Test how the workflow behaves with stale observations, missing records, failed repairs, and recurring mismatches. For an AI-enabled application, evaluate both decision quality and whether its execution controls respect those conditions.
My reconciliation work made the problem concrete: copying customer data into a marketing platform is not the same as establishing that the platform holds the intended state. A separate comparison-and-correction path is needed because the delivery path can be incomplete, delayed, or wrong.
As AI takes a larger role in marketing workflows, that distinction becomes part of the decision architecture. Before trusting an automated action, teams should be able to say which customer fields were checked, against which authority, at what time, and what happened when they disagreed.