AI adoption is moving faster than enterprise readiness and recent data highlights just how far behind infrastructure is. Stack Overflow’s 2025 Developer Survey found that 84% of developers are using or planning to use AI tools in their development process. Even with growing adoption, many organizations still have yet to build the context infrastructure needed for agents to operate reliably.
This issue is becoming increasingly important as organizations move from AI assistants that answer questions to agents that make decisions autonomously. A model can only be as effective as the context around it, so when a workflow is unclear, ownership is fragmented, or the knowledge required to make a decision is scattered across systems, an agent may generate seemingly confident responses that appear correct, but ultimately fail in practice.
As enterprises move from experimentation to deployment, operationalizing context must become a business priority.
Identify where context lives
The first step in operationalizing context is to locate it. In most enterprises, context is spread between structured systems, such as tickets, records, approvals, policies, and transaction history; unstructured content, such as emails, notes, documents, and chat history; and human judgment, which represents the knowledge experienced employees rely on when the written process is incomplete.
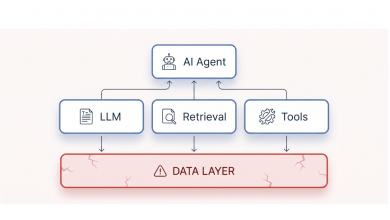
The problem is that this context rarely aligns. A policy may exist in one system and the exception to that policy may live in someone’s inbox, so the actual best practice may depend on the engineer who is accountable for the project. If an agent only has access to partial context, it often misses the whole picture.
Map the process
Workflow mapping should come before agent deployment. As part of this, organizations must understand the processes employees actually follow, not just the ones captured in documentation. In many cases, those two versions are meaningfully different in that documented versions are standardized and well-organized, and real versions include exceptions, workarounds, approvals, and judgment calls.
This is where task mining, structured interviews, and process walkthroughs become useful. These exercises help identify where decisions are deterministic and where they depend on context. Some steps should be automated with rules, while others require agentic judgment. If those guardrails are not determined early, the organization risks building a system with the wrong kind of autonomy.
Define what counts as trusted context
Once the workflow is mapped, the next step is understanding what information should be trusted by the agent. Not all context should be treated equally. Some sources are authoritative, some are helpful but incomplete, and some may already be out of date.
This is where many enterprise deployments break down. Teams connect the agent to too many sources without defining which ones are canonical. The result is a system that can retrieve a large volume of information, but has no reliable way to decide what should shape its next action. For production use, context needs authority, recency, and scope.
A practical approach is to assign each context domain an owner, a validation cadence, and a freshness rule. For example, a pricing policy may need frequent review, a benefits policy may need legal sign-off before it changes, or a customer support playbook may need weekly updates to reflect new products, escalations, or exception-handling rules. Context management becomes much more reliable once each source is treated according to its business risk.
Build validation into the pipeline
Operational context cannot be a static knowledge base. It needs an update loop so that when a policy changes, an exception is approved, or a process shifts, the change should flow through the same system that the agent uses in production. If it doesn’t, the agent will continue acting on stale assumptions.
This means validation should happen at ingestion. Metadata such as source, owner, date, or version should be added to knowledge bases before it reaches the agent layer. The goal, in addition to finding information faster, is to make sure the agent can distinguish between a current rule, a historical reference, and unverified information.
Human review is also essential at this stage.Agents can surface patterns, but domain experts need to resolve conflicts, confirm exceptions, and approve updates to high-importance tasks. The more operationally sensitive the workflow, the more important the review step becomes.
Design for audit and recovery
AI agents should be reconstructable. If an agent routes a case incorrectly, approves the wrong request, or triggers a downstream action, the organization should be able to explain what context it used and why the decision occurred.
This requires understanding the sources consulted, the version of the content, the permissions applied, and the action taken. It also requires a recovery path. When context proves incomplete or incorrect, the organization should have a clear process to correct the source material and prevent the same error from repeating.
In regulated settings especially, auditability is not optional. But even outside regulated industries, the ability to trace context is what turns a prototype into a dependable system.
Start with a defined use case
The most effective enterprise deployments usually begin with narrowly defined workflows to ensure a clean boundary for learning. Optimal starting points tend to be areas where the right answer is knowable, the context is bounded, and failure is visible.
For example, procurement approvals, internal support triage, onboarding workflows, and compliance checks are often better starting points than open-ended knowledge work. In each of these cases, an organization can define which context matters, who owns it, and how success will be measured, making it possible to improve the system deliberately. By contrast, broad workflows can obscure whether the problem is the model, the context, or the process itself.
In intelligent revenue cycle management, AI systems constantly learn from payer policies, clinical documentation, coding practices, appeals, and human feedback. In one instance, billing and collections for more than 150 clinics, managing 500,000 patients and processing 1.5 million annual claims were transformed. The clean claim rate for these clinics jumped from 82% to 94% and claim rejections were significantly reduced, shortening the overall revenue cycle.
Scale through ownership
Once a use case is set, the next challenge organizations must tackle is ownership. As more agents are added, context must stay updated across workflows, teams, and systems. This can only happen when there is clear accountability for the knowledge domains the agents depend on.
In practice, this means naming owners, defining update rules, and setting review cadences across functions such as operations, compliance, legal, and data. Context should be managed and updated in real time. If no one owns the source of truth, the system will drift.
This is also where alignment with business leaders is essential. The people who understand the work best should help shape the context layer because they know where exceptions live and what information actually changes decisions.
Make context the operating layer
Making context visible, governed, current, and auditable is what allows organizations to operationalize the knowledge that makes agents useful. Enterprises that do this well may not necessarily have the flashiest AI systems, but they will have the most dependable ones.