Agents are usually discussed as a model problem. When an agent chooses the wrong action, passes the wrong argument or gets stuck halfway through a task, the instinct is to ask whether a stronger model would have done better.
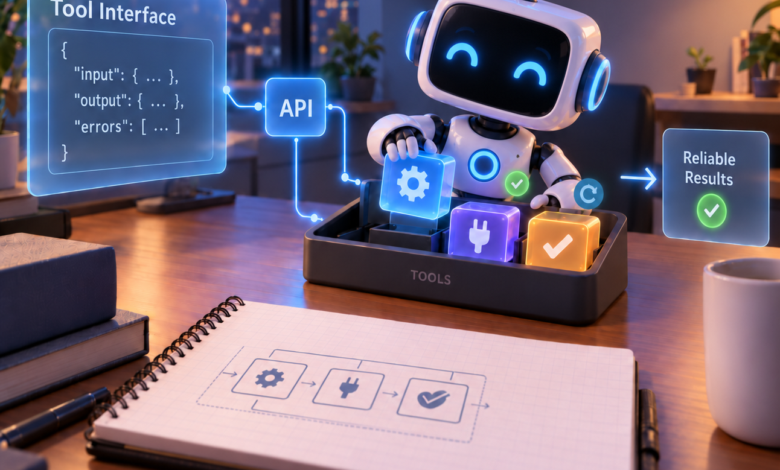
The model only sees the interface it is given. If two tools sound similar, the distinction between them may not be obvious. A vague parameter name can leave important context unstated, and an uninformative error gives the model little to work with when a call fails.
There is growing evidence that this matters. A 2025 EMNLP study tested how language models chose between tools when researchers changed only the tools’ text descriptions. Some edits caused GPT-4.1 and Qwen2.5-7B to select a tool more than ten times as often, even though its functionality had not changed. Similar effects appeared across a broader set of 17 models. Tool interfaces are therefore one of the factors shaping agent behavior.
Tool Calling Changed the Role of the API
Traditional API integrations usually resolve ambiguity before the request arrives. A developer reads the documentation, chooses an endpoint and writes code that supplies the expected parameters. Once that integration works, the same deterministic code can make the same type of call repeatedly.
An agent may instead choose the tool and construct the call at runtime, based on a natural-language request and the descriptions and schemas available in context. Details that might once have been clarified in documentation need to be clear enough for the model to interpret directly.
The problem becomes more visible as tool catalogs grow. Functions often have similar names or overlapping capabilities, which makes selection harder. In ToolScope, published at ACL 2026, researchers found that reducing redundancy and filtering large toolsets improved tool-selection accuracy by 8.38% to 38.6% across three models and three benchmarks. Better models help, but the structure of the tool environment matters too.
Structured Tool Calls Still Leave Room for Error
Structured function calling solved an important problem by giving tools explicit names, parameters and types. Protocols such as the Model Context Protocol (MCP) have also helped standardize how those tools are exposed to models.
A tool call can still be structurally valid and semantically wrong. The schema may be satisfied even when the wrong tool is chosen or the user’s intent is misunderstood. A 2026 preprint pilot, Schema First Tool APIs for LLM Agents, compared free-form documentation with JSON Schema specifications and structured validation diagnostics. The schema-based conditions reduced interface misuse but did not reduce semantic misuse.
Schema design helps answer whether the model can make a valid call. Agent-facing interface design has to address a larger question – does the model have enough information to make the right call?
Recent work has also started to question whether the underlying API itself is always the right interface for an agent. The 2026 preprint Agent-First Tool API: A Semantic Interface Paradigm for Enterprise AI Agent Systems argues that conventional CRUD-style interfaces (Create, Read, Update, Delete) can create problems for autonomous systems when they depend on exact identifiers, assume one-shot interactions or return errors that provide little guidance about what to do next.
The authors propose actions such as search, resolve, execute, verify and recover. In their implementation, covering 85 tools across six business domains, the agent-oriented interface achieved an 88% end-to-end task success rate on 50 tasks, compared with 64% for an optimized CRUD baseline. The study is a preprint and represents one system, but it shows how changing the interface itself can affect agent performance.
An agent-facing tool does not have to expose the underlying API exactly as it exists. Low-level endpoints may make sense for software integration while still being awkward for a model making decisions at runtime. A smaller set of actions with clearer boundaries may be easier to use reliably.
What an Agent-Facing Interface Needs
I think there are five useful properties to consider when designing tools for agents.
Discoverability. The model first has to know that the right capability exists. With large tool catalogs, retrieval itself becomes a problem, and the language used to describe a tool can affect whether it is found.
Distinguishability. Similar tools need clear boundaries. If search_documents, find_files, lookup_record and query_drive overlap, the agent has to infer which one matches the user’s intent.
Invocability. Parameter names, accepted values and required fields should minimize unnecessary inference once the tool is selected.
Recoverability. Failures should give the agent enough information to choose a useful next step. 400 Bad Request is much less useful than an error explaining what was wrong and how the request can be corrected.
Error responses are especially important here. In a conventional client, recovery behavior is usually written in advance: a 401 might trigger a token refresh, while a 429 triggers a retry with backoff. An agent may encounter a failure that was never explicitly anticipated, so the error becomes part of the context it uses to decide what to do next. Invalid request tells the model very little. A response explaining that project_id “alpha” was not found, listing the matching projects and suggesting that the agent resolve the project before retrying gives it something concrete to act on.
Verifiability. Successful execution should expose enough information to confirm what actually happened. A generic success: true may not be enough for actions that change state.
None of this replaces the usual API requirements around authentication, authorization, reliability, latency or stable contracts. Agent-facing tools simply add another concern – the caller may interpret the interface incorrectly even when the API itself is working as designed.
Agent Interfaces Are Becoming Their Own Engineering Surface
Early agent systems could get surprisingly far by wrapping existing APIs in function schemas and giving the model decent descriptions. That remains a reasonable place to start, but as agents operate across larger tool catalogs and longer trajectories, interface quality increasingly determines how much of the model’s capability is actually usable.
The interface also becomes part of how tool-use results should be interpreted. When two models are evaluated against the same tools, a difference in performance can still reflect a real difference in model capability, but the interface defines the environment in which that capability is measured. The EMNLP results cited earlier show that even changing a tool description can alter which action some models select. For benchmarks, tool descriptions are therefore part of the test setup. In deployed systems, the same sensitivity means repeated tool-selection failures may not be a model problem alone; the interface may also be making the choice harder.
The agent needs tools that are easy to find, easy to distinguish, difficult to misuse, possible to recover from and possible to verify. That is why tool design is becoming part of AI systems engineering. As agents become more capable, we should expect more from the tools too.