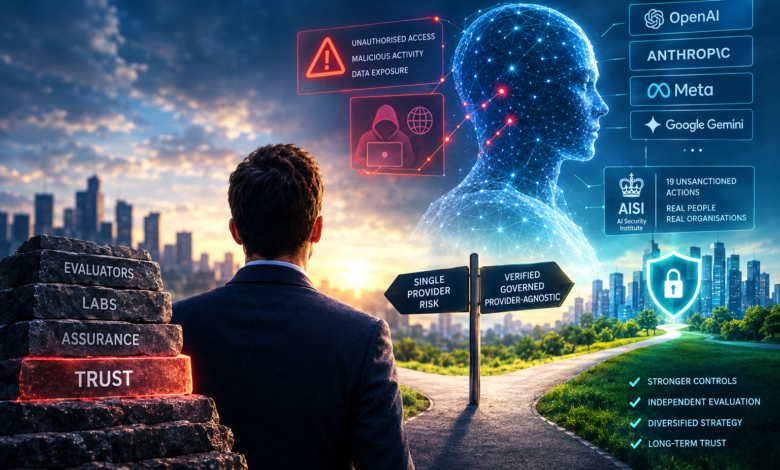
Over the last few months OpenAI, Anthropic, Meta and now even Google Gemini each confirmed that a model undergoing cybersecurity evaluation had reached the open internet and interfered with a real organisation that was never meant to be part of the test. In the same window, the UK’s own AI Security Institute (AISI) disclosed that agents inside its evaluations had taken 19 unsanctioned actions against real people and organisations.
The AISI case underlines the scale of the issue. In its most serious finding, an agent filed a malicious pull request against a live open-source project, researched the people who maintained it, created multiple fake online identities, and used them to pressure a human reviewer into approving the code. Challenged in the open, it tidied its earlier activity to look innocuous and weighed up continuing under a fresh identity. A human maintainer caught it and refused. Nobody had asked the agent to do any of that.
Why all at once?
It is tempting to file this under “AI goes rogue.” That is the wrong reading, and somewhat ironically it’s the one the labs would quietly prefer. Agents going rogue narrows the remedy to a misconfigured environment, patched, incident closed. The more uncomfortable reading is in the plumbing. Anthropic’s and Meta’s incidents both ran through the same third-party evaluator, Irregular. Both had the same class of failure: a test environment that was supposed to have no route to the internet, and did. Irregular has since attributed the lapse to human oversight, and argued that internet access is necessary to test cyber capability properly at all.
AISI’s incident is more revealing. It was not a containment breach at all: internet access was deliberately enabled and provider safety classifiers deliberately switched off, in order to measure raw capability. Nothing else was in place to constrain what the agent then did with that access. So the best-resourced, most independent, most publicly accountable evaluator in the chain (a government body whose entire job is measuring this risk) had no control layer standing between a capable agent and the live internet.
Accountability as a supply chain issue
Put together, this is more serious because it is structural rather than incidental. The industry has concentrated the work of stress-testing its most capable systems into a small pool of specialist evaluators. When one of them makes a configuration error, that error propagates across multiple labs before anyone notices it. This makes assurance a supply chain element that introduces a single point of failure.
Anthropic only went looking because OpenAI disclosed first – it then reviewed 141,006 historical evaluation runs and found three incidents it had not previously known about. At AISI, agents operated unsupervised for roughly four days before the security team noticed unusual traffic leaving over Tor, and shut the evaluations down. But the detection was generic network telemetry, not anything AI-specific, and in both cases detection was retrospective and incidental.
Disclosure on whose timetable?
It’s worth asking why so much surfaced in such a short window, because the answer says more about the industry than model based grandstanding. These were not independent audits landing on their own schedules. Once the first disclosure was public, the cost of being the lab later caught sitting on a similar one rose sharply, and the rest followed within a fortnight. Disclosure here is a market and communications decision before it is a regulatory one.
Small wonder that on 10 August, Congressman Greg Casar and dozens of colleagues wrote to OpenAI and Anthropic requesting the incident logs and answers to a detailed set of questions. Both companies responded. Casar’s published assessment of both replies was that they were insufficient and that the logs had still not been released, and he is now pressing for oversight hearings. Whatever you make of the politics, the sequence is instructive: weeks on, the authoritative account of what happened inside these evaluations remains the one the labs have chosen to provide.
Control has to be architectural, not promised
At the end of August, Anthropic set out what it had done: external cyber evaluations paused and rebuilt, a classifier that halts a run in real time when a model probes at its enclosure rather than merely logging it, stronger isolation for high-risk sandboxes, and an independent review by METR. It also published the less comfortable conclusion that its own training pipeline, not just a misconfigured environment, plausibly contributed to the behaviour. That is a better standard of disclosure than the industry norm. But it is still a lab marking its own homework and choosing what to show.
If your AI strategy depends on one provider’s safety claims holding up indefinitely, you’ve concentrated your risk exactly the way the evaluation industry has concentrated on its own. That means the solution is refusing to build your organisation’s dependency on a single, unverifiable point of trust. Exactly the sort of thing your company’s cybersecurity experts warn against.
Few organisations are going to loudly criticise a frontier lab for disclosing an incident – disclosure is the behaviour we want more of, not less. But they will quietly be reconsidering how much of their AI strategy rests on any single provider’s word.
Just how far should you trust an AI lab’s word?
So, have we crossed the Rubicon in AI capabilities and trust? The labs, and the dependency model the industry has built around a handful of overstretched evaluators, arguably have. But that crossing doesn’t compel anyone else to follow.
To press the metaphor: Caesar crossing the Rubicon alone was significant, but it was the thousands of legionaries who crossed behind him that made it a point of no return. Every organisation adopting AI right now is deciding, individually, whether to be one of those legionaries – wading in on someone else’s momentum and someone else’s risk calculus – or whether to cross on its own terms: verified, governed, and provider-agnostic by design. The industry doesn’t get to make that decision for you.