Artificial intelligence investment continues to accelerate, with worldwide spending on AI expected to reach $2.5 trillion by 2028. Yet many enterprise AI initiatives still struggle to move beyond experimentation and into production environments.
The issue is rarely a lack of ambition. Most organizations understand the competitive pressure to adopt AI, and many have promising pilots underway. The harder question is whether they can safely provide AI systems with the data needed to produce meaningful results in real business conditions.
AI models are only as effective as the data used to train, test and validate them. Many proof-of-concepts rely on dummy datasets, heavily masked records or synthetic data that has not been sufficiently validated against its intended use. These approaches can support experimentation, but their value depends on how well they preserve the relationships, variability and edge cases that influence production behavior. Newer generation techniques are improving that fidelity, but organizations still need evidence that the resulting data is representative, privacy-safe and fit for purpose.
As a result, AI projects that appear successful in controlled settings can break down once connected to real workflows. The model may work, the business case may be clear and internal appetite may be strong, but the path to production becomes crowded with security reviews, data access approvals, compliance questions and uncertainty over how much autonomy AI systems should have.
Why AI Proof-of-Concepts Stall Without Production-Representative Data
Many AI pilots begin with technical momentum, but friction often appears when teams introduce production data, connect models to real workflows or expand access beyond a controlled test environment.
This disconnect creates a false sense of confidence. A proof-of-concept can look successful while avoiding the very conditions that determine whether AI will work in production: sensitive data, messy workflows, inherited systems, inconsistent permissions and unclear ownership.
Real enterprise data is messy. It contains missing values, inconsistent formatting, duplicated records, outliers, and rare scenarios that can significantly influence model behavior.
Research continues to show how critical data readiness is to AI success. 43% of leaders cite data readiness as the biggest barrier preventing AI initiatives from aligning with business objectives. Data quality and integrity also remain among the most common priorities for organizations scaling AI programs.
The problem becomes more significant when training environments differ too sharply from production conditions. Google has identified training-serving skew as an important source of machine learning failure, advising that training and production environments resemble each other as closely as possible.
When organizations avoid realistic data during experimentation, they often create systems that perform well in demos but fail under operational pressure.
Sensitive data is a major reason this gap exists. Enterprise datasets often include personal identifiers, financial records, healthcare details, intellectual property and confidential operational data. Security, legal and compliance teams are right to be cautious, but that caution can create friction when AI teams need realistic data to validate performance.
The result is an AI development process built on incomplete representations of reality. Organizations that want AI proof-of-concepts to succeed in production need governed access to data that preserves the operational context, relationships and variability that influence real-world performance. Depending on the use case, that may include protected real data, rigorously validated synthetic data, or a combination of both. The important distinction is not simply whether data is real or synthetic, but whether it is representative, appropriately protected and demonstrably suitable for the intended workload.
Where AI Experimentation Introduces Data Exposure Risk
Access to realistic data is essential for meaningful AI experimentation, but early-stage AI workflows can also introduce significant security and governance risks.
In many organizations, proof-of-concept environments move faster than formal governance processes. Development teams may create temporary pipelines, cloud storage locations, notebooks, or feature repositories before security controls are fully implemented. Sensitive data can quickly spread across systems and teams during experimentation.
AI workflows often involve multiple technologies and collaborators. Data may move between production systems, cloud platforms, analytics tools, vector databases, third-party AI services, logs, staging environments and backup systems. Every additional copy creates another exposure point and another governance question: where did the data move, who can access it and how long should it be retained?
This complexity becomes difficult to manage when organizations rely on inconsistent protection strategies across environments.
The Hidden Cost of AI Friction
The risk is not only that AI projects slow down. It is that organizations begin making quiet compromises to get them across the finish line.
A team may reduce the scope of an AI agent, limit the datasets it can access, require more manual review or remove higher-value functionality before launch. Those decisions may be prudent from a risk standpoint, but they can also weaken the business value of the system. Over time, enterprises may find themselves deploying AI that is technically in production but far less capable than what was originally envisioned.
This creates a difficult cycle: AI teams need trusted data and appropriate access, while security and compliance teams need assurance that sensitive information remains protected. When those needs are not reconciled early, timelines stretch and the final system becomes less useful.
The challenge grows further as regulatory scrutiny surrounding AI and data governance increases globally. Organizations must navigate evolving privacy frameworks, industry regulations, contractual obligations, and internal governance requirements while continuing to innovate.
Protecting sensitive information after it has spread across AI workflows is significantly harder than applying controls earlier. Embedding protection at the beginning of experimentation helps reduce risk while allowing teams to work with more representative datasets.
Making Sensitive Data Safe and Usable for AI Development
Organizations do not need to choose between innovation and data protection. The more effective approach is to preserve the usefulness of data while reducing unnecessary exposure.
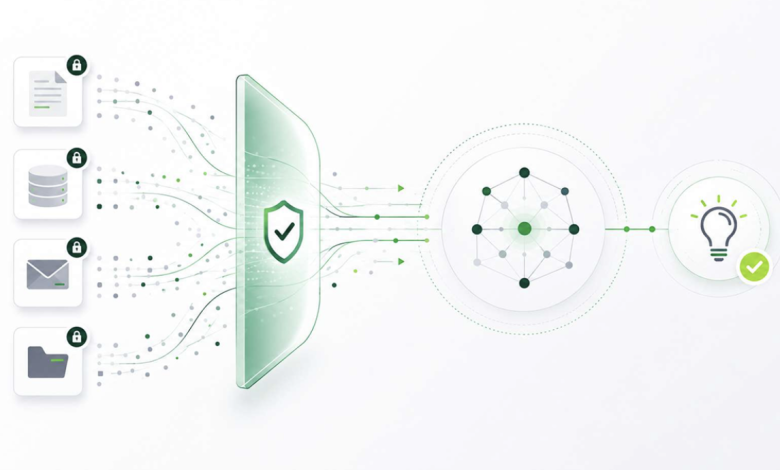
Tokenization is one technique increasingly used to support this balance. The UK Information Commissioner’s Office describes tokenization as a process that replaces identifiers with randomly generated tokens while separating the original sensitive values from the protected dataset. This approach can help reduce exposure risk while preserving data usability for analytics and large-scale processing.
When applied correctly, tokenized real data can preserve important characteristics of production environments, including relationships between records, referential integrity, operational inconsistencies and edge cases. That matters because AI systems rely heavily on patterns and contextual relationships, not just isolated values.
Format-preserving protection techniques can also help protected data behave like production data inside AI pipelines and downstream systems, without directly exposing regulated values.
Protected real data can also provide a trusted foundation for evaluating other development datasets. By preserving important relationships and edge cases while shielding sensitive values, it can help teams use newer generation techniques to expand coverage without assuming that realism or privacy comes automatically.
Tokenization is not a universal solution. Pseudonymized data may still fall under regulatory requirements depending on how it is used and whether reidentification remains possible, so governance remains essential.
The goal is not to bypass governance, but to make governance workable at AI speed. If access is granted too broadly, risk increases. Scalable AI programs need a middle path that allows protected data to move through approved workflows with visibility, policy enforcement and auditability.
Organizations typically need layered protections that include access controls, policy enforcement, auditability, token-vault separation, and field-level decisions about which data should be tokenized, generalized, anonymized, synthesized or excluded entirely.
Synthetic data also has an important role in AI development, including experimentation, benchmarking and the creation of underrepresented scenarios. As newer generation techniques improve its fidelity and coverage, organizations should still validate it for privacy, utility and fitness for the intended use. For higher-impact applications, protected real data may remain an important validation point.
Data-centric protection strategies help organizations move beyond the assumption that security slows innovation. When protection follows the data itself rather than relying only on perimeter defenses, teams gain more flexibility to experiment safely across cloud platforms, analytics tools and AI development environments.
Reducing Friction Between AI Innovation and Production Reality
AI initiatives rarely stall because organizations lack interest or investment. More often, they slow down because teams cannot safely operationalize the data needed to validate performance under real business conditions.
Moving AI from proof-of-concept to production requires more than selecting the right model architecture or experimenting with the latest tools. It depends on whether organizations can reduce the friction between AI systems, sensitive data, governance requirements and production workflows.
Dummy datasets may be sufficient for demonstrations, while rigorously generated synthetic data can support much more demanding development, testing and training scenarios. Advances in adaptive generation and validation are improving the ability of synthetic datasets to preserve important patterns and intentionally expand coverage of rare conditions. Even so, organizations should establish measurable evidence of fidelity, privacy and downstream utility, and consider protected real data as a controlled validation point when the risk or operational context requires it.
Organizations that embed protection directly into the AI development lifecycle are better positioned to bridge the gap between experimentation and production. When teams can safely use realistic data earlier in development, AI proof-of-concepts become more reliable, scalable and production-ready.
Conclusion
The AI initiatives most likely to succeed will treat data protection as part of the production path, not a late-stage review. Reducing friction around sensitive data may become one of the most important factors in determining which AI programs move from promising pilots to real enterprise impact.