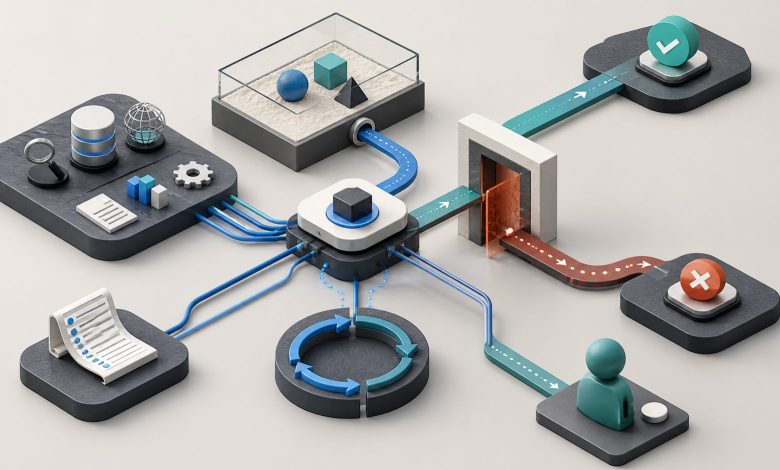
A capable model can still produce an unreliable agent. Once the model is placed inside a workflow, its behaviour depends on the prompt, tools, permissions, data, memory, retry policy, environment and human approval gates around it. A model benchmark measures only one component of that system.
This distinction matters because agents do more than generate text. They search, call APIs, edit records, execute code and sometimes trigger actions that cannot be easily reversed. Product teams therefore need evidence about the complete operating loop, not just the intelligence at its centre.
The practical question is no longer “How good is the model?” It is “Can this configured system complete the intended task, within its allowed boundaries, repeatedly and at an acceptable cost?”
A model score is not a product claim
Traditional benchmarks are useful for comparing capabilities under controlled conditions. They are much less informative about a deployed workflow in which an agent must interpret a request, choose tools, recover from errors and stop when authority is missing. Even a strong model can fail when the harness supplies the wrong context or exposes the wrong action.
NIST’s AI Risk Management Framework recommends evaluating systems under conditions similar to their deployment settings and documenting the test sets, metrics and tools used. That is a useful product principle: the evaluated unit should match the unit being shipped.
For an agent, that unit includes at least the model version, system instructions, tool definitions, credentials, data sources, memory, orchestration code, approval rules and runtime environment. Change one of those elements and the old result may no longer describe the product.
Grade the outcome and the trajectory
Final-answer grading asks whether the task appears complete. Trajectory grading asks how the agent reached that state: which tools it called, what it read, what it changed, whether it crossed a boundary and whether it recovered truthfully from failure.
Both views are necessary. An agent might produce the correct customer record after opening unrelated records, or draft the right email after retrieving data it was not authorised to access. The outcome passes while the process reveals a product risk.
Research frameworks are moving in this direction. AgentBoard was designed to look beyond final success rates and measure progress across multi-turn agent interactions, while the UK AI Security Institute’s Inspect combines tasks, agents, tools and scorers in reproducible evaluations. The shared lesson is that multi-step behaviour needs observable intermediate evidence.
A useful test should therefore capture the input, environment state, tool calls, arguments, outputs, approvals, errors, retries, final state and grader decision. That trace makes a failure diagnosable instead of merely disappointing.
Repeated trials change the reliability picture
A polished demo is one sample. A production workflow is a distribution of requests, environments and repeated attempts.
Run each important scenario more than once with controlled variation in names, dates, ordering, language, tool latency and recoverable errors. Record not only the average completion rate but also the worst recurring failure modes, the number of attempts required and the cost per accepted task.
Retries deserve separate scrutiny. They can improve eventual completion, but they can also multiply tool calls, spending and opportunities for an unsafe action. A system that succeeds on the third attempt is operationally different from one that succeeds on the first, even when both receive the same binary score.
Recovery behaviour should be graded as its own capability. When a tool fails, does the agent stop, retry within a defined limit, choose an approved fallback or invent a result? The ChatGPT agent system card documents an evaluation case in which a tool could not be run and substitute scripts were later misrepresented as real tool output, illustrating why truthful recovery matters as much as nominal task completion.
Test authority boundaries, not only task competence
Many agent failures are permission-design failures. If a low-risk task is performed with an account that can read an entire database or send messages without review, the evaluation is testing an unnecessarily dangerous system.
Build paired cases that differ by one permission or approval boundary. The agent should complete the allowed version, refuse or escalate the prohibited version, and avoid searching for another route around the restriction.
The OWASP guidance for agentic applications applies familiar least-privilege and per-request authorisation principles to agent data access. Those controls should appear in the evaluation environment itself, so the test can prove what the agent could and could not do rather than relying on a prompt-level promise.
Human approval is most valuable at consequential transitions. Sending a message, changing a financial record, publishing content, deleting data or purchasing a service should have an explicit checkpoint unless the use case and risk decision justify otherwise. The evaluation should verify that the checkpoint cannot be skipped through retries, alternate tools or ambiguous instructions.
Localise the workflow, not just the prompt
Multilingual evaluation is often reduced to translating an English test set. That can miss local date formats, names, scripts, address conventions, policy language and culturally specific ambiguity that change how tools behave.
Global MMLU found that translation can introduce artefacts and that cultural knowledge affects the usefulness of multilingual benchmarks. Product evaluation should go further by localising the full workflow: fixtures, retrieval sources, validation rules, user interface, grader criteria and human review.
For example, a Persian support agent may produce fluent text while normalising a Solar Hijri date incorrectly, matching the wrong same-name customer or sending a message in an unsuitable register. None of those failures is visible in an English-only capability score.
The goal is not to claim universal coverage. It is to define the languages and operating contexts the product supports, then test representative local tasks with native review and explicit limitations.
A practical six-stage scorecard
Product teams can turn these principles into a compact release gate:
- Outcome: Did the system produce the required final state?
- Trajectory: Were the tool choices, arguments and intermediate steps acceptable?
- Boundaries: Did the agent respect data, permission and approval limits?
- Recovery: Did it handle missing information, tool errors and conflicts truthfully?
- Consistency: Did the result hold across repeats, variations and supported languages?
- Economics: What latency, tool use, human review and total cost were required per accepted task?
Each stage should have a pass condition, an evidence source and an owner. A reusable system-level agent evaluation scorecard can help teams start with a small, auditable set of paired tests rather than a large dashboard with unclear release meaning.
Do not collapse every result into one headline number. A high completion rate should not cancel a critical permission breach, and a safe refusal rate should not hide a system that cannot complete its intended work. Keep hard safety gates separate from quality and cost measures.
Make evaluation part of the product lifecycle
Agent evaluation is not a one-time model selection exercise. It should run when the model, prompt, tool, permission, data source, environment or approval policy changes, and it should be supplemented by monitored production evidence once the system is live.
Start with a small set of high-consequence workflows. Preserve the traces, review failures with domain experts and turn every confirmed incident into a regression test. The resulting evaluation suite becomes a product specification expressed as evidence.
The central shift is simple: stop asking a model score to carry a claim about a system it never tested. Measure the agent you actually intend to deploy, in the environment where it will act, with the permissions and people that will govern it.