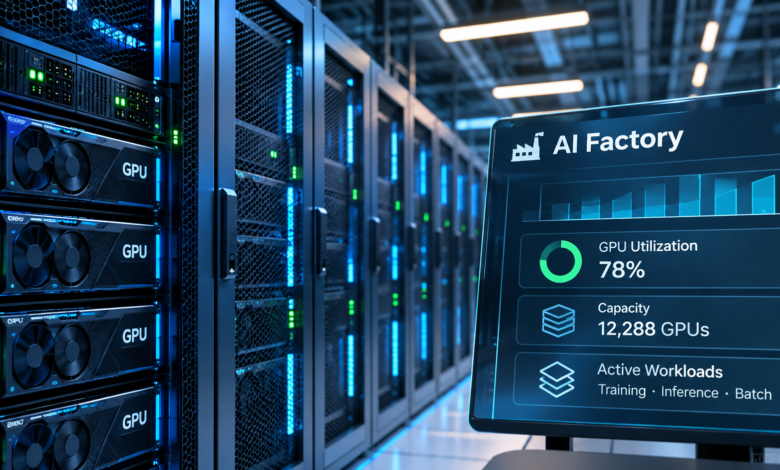
A data center operator can fill a room with expensive GPUs and still struggle to build a sustainable business. The machines may be ready for training runs and inference requests, but that doesn’t mean customers are ready to use them.
This is the commercial challenge behind the AI factory model. The familiar debate focuses on chip supply, electrical capacity and cooling. Those constraints are real. Yet once the hardware is installed, operators face another problem: converting available compute into paid, reliable service.
A facility’s business case depends on the gap between what its hardware could deliver and what customers actually buy. Closing that gap takes decisions about hardware, software, pricing and demand long before the first server goes live.
What Makes an AI Factory Different?
A conventional data center may host business applications, storage and general-purpose servers. An AI factory is designed around the movement and processing of data for AI workloads, from model training and fine-tuning to ongoing inference.
That changes the physical design. High-density GPU systems create demanding power and cooling requirements. Training clusters need fast connections between servers and enough storage bandwidth to keep processors fed. Production inference systems must respond quickly and consistently as users send requests.
It also changes the operating model. An AI factory needs a way to provision servers, monitor faults, manage different customers and bill for the capacity they consume. A cluster that works in a benchmark may still be difficult to offer as a commercial service.
For investors and operators, this difference matters. Buying the hardware produces capacity. Running a service requires customers, software and the ability to deliver what was sold.
Why Idle GPUs Create Pressure on the Business
GPU hardware is expensive to acquire, and its value can change quickly as newer systems reach the market. An operator that finances a deployment must meet those obligations whether every server is busy or not.
Some costs rise with use, particularly electricity. Others continue when demand is weak. Site leases, network connections, staffing, maintenance contracts and financing payments don’t disappear when a customer cancels a reservation.
Three problems often appear together:
- Fixed commitments remain. Racks, power infrastructure and financing can create costs that are difficult to reduce when utilization falls.
- Unsold hours cannot be stored. An empty GPU slot today can’t be sold tomorrow as yesterday’s capacity. The opportunity to earn from that hour is gone.
- Headline rental prices hide the margin. Revenue per GPU hour means little without accounting for electricity, depreciation, support, networking and fees paid to sales channels.
This is why utilization deserves as much attention as the number of accelerators installed. Even that measure needs care. A GPU running internal tests all day may be technically busy while producing little billable revenue.
Operators need to distinguish between allocated capacity, work completed and paid usage. Each tells a different story.
The Workload Should Determine the Hardware
It’s tempting to design a facility around the newest available accelerator. But a customer paying for large-model training needs a different setup from a company serving a smaller model to thousands of users.
Three common workload types illustrate the trade-offs:
- Large training jobs often require clusters with fast GPU-to-GPU connections, dependable storage throughput and enough uninterrupted time to finish long runs.
- Production inference places weight on response time, consistent availability, memory capacity and cost per request. The most expensive accelerator may not be the best value for every model.
- Batch processing and experiments can sometimes run on spare or interruptible capacity, provided customers can tolerate pauses and restart work when needed.
These differences affect pricing. A customer reserving a dedicated cluster for several months offers predictable income but may expect a discount. On-demand users can pay for flexibility, although their usage may be harder to forecast. Interruptible jobs can help fill gaps, but operators shouldn’t treat them as dependable demand.
Hardware choice is therefore a sales decision as well as an engineering decision. A fleet with impressive specifications may be poorly matched to the workloads customers are willing to purchase.
Power, Networking and Software All Affect Revenue
Electricity is often discussed as a construction constraint: can the site secure enough megawatts to host the planned hardware? Operators also need to ask how much paid computing work can be produced within that power budget.
Cooling efficiency, power distribution and equipment placement affect the amount of energy available to processors. Network design affects whether a large training job can use many GPUs productively or spends time waiting for data to move. Storage performance can create the same problem.
Software makes these physical choices visible to customers. If provisioning a server requires repeated manual work, a buyer may wait hours for a machine that is technically free. If monitoring doesn’t detect failures promptly, the operator can lose billable time while a customer loses trust.
Reliable provisioning, remote management, usage reporting and billing may receive less attention than GPU model numbers. They determine how easily the facility can deliver and charge for compute, especially when customers use different hardware configurations.
Customer Demand Needs to Be Part of the Design
Traditional data center businesses often earn money by leasing space, power and connectivity. Selling GPU compute introduces a different relationship. Customers expect a functioning service, clear pricing, technical support and a way to start workloads without negotiating every server allocation.
That requires distribution. Operators may sell directly to AI companies, supply capacity to cloud platforms or work with marketplaces that already have buyers. Each route affects margins, customer access and control over the service.
Hydra Host provides dedicated bare-metal GPU infrastructure and supports data center operators with planning, procurement, provisioning and access to compute customers. Its AI Factory offering connects those activities through an accelerator program and its Brokkr platform, which manages infrastructure and helps operators bring capacity to market.
The wider lesson is that customer acquisition cannot be left until construction is finished. A location, power contract and choice of GPUs should be informed by the workloads that buyers need and the terms on which they will commit.
A site built for long training reservations may need a different commercial plan from one serving bursty inference traffic. Both can work, but mixing them without a capacity plan can leave expensive machines underused or create service problems for customers who need predictable access.
The Metrics That Reveal Whether an AI Factory Works
A single utilization percentage doesn’t describe the health of a GPU business. Operators need measures that connect technical performance with cash flow.
A useful operating dashboard should track:
- Billable GPU hours: How much available capacity customers actually pay to use, separated by hardware type and contract.
- Revenue after direct costs: What remains after power, networking, support, platform fees and other costs tied to delivering the service.
- Time to provision: How long it takes from a customer’s request to a usable server or cluster.
- Service reliability: How often jobs are interrupted by hardware, network or storage problems, and how long recovery takes.
- Demand concentration: How much revenue depends on a small number of customers or one type of workload.
These measures can expose problems that a busy GPU fleet conceals. A highly utilized cluster may generate weak margins if pricing is too low. A premium server may earn little if customers cannot get it configured quickly. Strong demand from one buyer can mask the risk of that contract ending.
Operators should also test their assumptions before expanding. What happens if a major customer delays deployment? Can capacity be offered in smaller units? Could a different GPU type serve the same workload at a lower cost? Those answers can change the case for buying another rack.
Scale Comes After Repeatable Operations
The strongest operating model is one that can take a new machine from installation to paying workload with little manual intervention. That means standardized server images, clear diagnostics, fast replacement procedures and pricing that reflects what each configuration costs to run.
It also means knowing when not to expand. A facility with open capacity and an uncertain customer pipeline may be better served by improving scheduling, product packaging and sales relationships than by ordering another shipment of accelerators.
An operator considering its next buildout should be able to answer a simple question with actual data: how many paid GPU hours will the additional hardware deliver, at what net margin, and under which customer commitments? That forecast is a stronger basis for investment than the size of the proposed GPU fleet.