
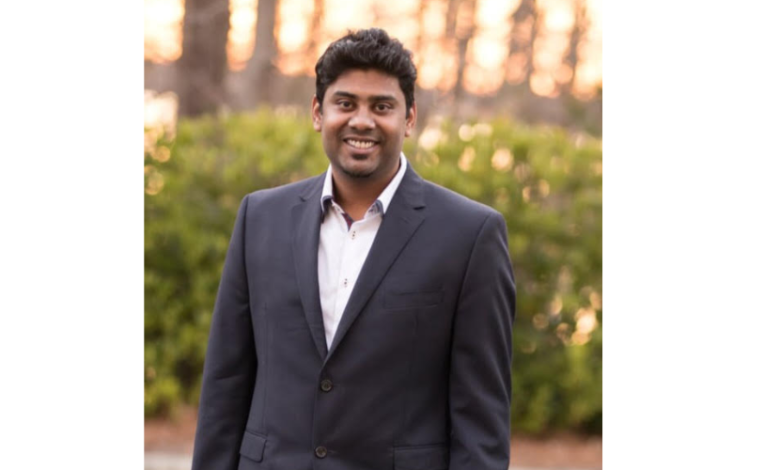
For Anudeep Katangoori, successful AI projects start long before a model is deployed. With more than 14 years of experience across data, cloud, and AI, he has worked on enterprise systems in transportation, retail, healthcare, finance, e-commerce, and telecom, giving him a broad view of what helps AI initiatives succeed and where they tend to break down.
His work has included building data platforms and AI foundations for use cases such as predictive maintenance, anomaly detection, operational analytics, and real-time decision support. That experience has shaped a practical approach centered on strong data foundations, clear ownership, governance, and systems that can hold up outside of a controlled pilot environment.
In this interview, Anudeep discusses the lessons he has learned from scaling AI across complex organizations, the risks of fragmented data and disconnected projects, and what companies should get right before moving generative AI and other advanced systems into production.
You’ve spent more than 14 years working across data, cloud, and AI in industries ranging from transportation and healthcare to finance and retail. How has that experience shaped the way you approach AI projects today?
My body of work and experience has taught me that the challenge is rarely the model itself. Reflecting on projects that did not succeed, whether in retail, finance, or telecom, almost none failed because of a faulty algorithm. Instead, failures happened earlier, when data ownership was unclear, and multiple teams defined the same entity differently, or later, when a prediction appeared in a dashboard no one regularly consulted. Now, I begin projects with the end in mind.
Before any modeling discussion, I seek three answers: who uses the output, which system receives the action, and who is contacted if there’s an error at 2 a.m. If I can’t identify a person for all three, the project isn’t fully prepared; it’s just an experiment, and I prefer to call it that rather than pretend it’s an initiative. Working across different industries also breaks the illusion that your domain is unique. The terminology may differ, but the failure modes are the same.
One of the major initiatives you’ve worked on is the Fleet Intelligence Platform. What was the business problem you were trying to solve, and what role did you personally play in building the foundation for it?
The core issue was data fragmentation. Telemetry data from vehicles, maintenance records, fuel transactions, and hours-of-service logs each resided with their respective teams, effectively answering questions within their scope. However, no one could handle inquiries that spanned multiple datasets. Crucial questions for a carrier, such as predicting truck failures before delivery, identifying anomalous fuel spending versus route adjustments, or monitoring a driver’s risk profile trend, require integrating several data sources.
My role was to establish the foundation rather than creating the models. I developed the platform layer on Cloudera Data Platform, integrated with Vertex AI for training and deployment, standardized the table format, and made a key decision: all workstreams connect to a single device and asset spine, ensuring one canonical identity for each truck, maintained consistently.
That’s unglamorous work, which is why the third use case took weeks to set up instead of restarting the integration discussion from scratch.
Companies are under a lot of pressure to adopt generative AI quickly. Why do you believe organizations need to get their data and governance foundations right before they start scaling AI across the business?
Generative AI amplifies the risks of weak data foundations, making problems more severe rather than manageable. Governance isn’t just a compliance burden to be addressed after the fun part. It ensures the output can be justified. A key question for any executive planning to scale: if a regulator, a plaintiff’s attorney, or your biggest customer inquires about why the system generated a particular answer, can you trace back the process? Can you identify which sources and versions were used, who had access, what data was kept, and the legal grounds for collecting it?
If your answer is no, it means you lack an AI program and instead have a demo that accumulates liability.
Your work has supported use cases such as predictive maintenance, fuel anomaly detection, and driver risk analysis. What did you learn from bringing several different AI applications together on one shared platform rather than building them separately?
The biggest benefit of using one shared AI platform was that each new use case became easier to build because the core data and infrastructure were already in place. It also made it easier to compare signals across areas like maintenance, fuel use, and driver risk.
The trade-off is that shared systems require more coordination and can take longer to build initially. The lesson was that the upfront investment can pay off by making future AI projects faster and more connected.
For instance,a shared platform has a larger blast radius and requires more coordination. Without clear accountability for the shared layer, it tends to degrade, as teams patch around issues instead of resolving them. Enter this trade-off with awareness that you’ll sacrifice some early speed for long-term acceleration, and be committed to that choice.
You’ve also helped guide AI strategy across multiple transportation businesses. What tends to go wrong when different departments pursue AI independently, and how can companies create a more coordinated approach?
The real issue isn’t duplicated spending; it’s what people usually include in slides because it’s simple to measure and doesn’t offend anyone.
The real failure is that you end up with several vendors, several data extracts of the same source, several definitions of the same entity, and no one accountable for making them agree. Individually, every project is defensible. Collectively, you’ve built an integration problem that’s more expensive than all the projects combined. The second failure is pilots designed to impress rather than to run: no monitoring, no owner, no plan for the day the vendor changes a model version.
Effective strategies include a central platform with federated ownership, a unified data and identity layer managed by a clear owner. Implementing a single intake process ensures each proposal is evaluated uniformly, making priorities based on merit rather than politics. The specific use case remains with the business leader who understands it best. However, centralizing use cases can undermine the domain knowledge that makes them effective, as I have observed. Often, the central team becomes a bottleneck, prompting others to work around it.
Transportation brings real-world safety and compliance considerations that many other industries do not face. How does that change the way you think about designing and deploying AI systems?
Error costs are asymmetric and shape engineering choices. A false negative in product recommendations results in a missed click, while in driver risk or predictive maintenance, it could lead to a collision. Therefore, setting the decision threshold isn’t merely a data science problem; it’s a business decision about which error is acceptable. Operations and legal teams should inform this decision.
I follow three basic rules. If an AI system could affect someone’s record or livelihood, a human should make the final decision. If it is used in a safety-related setting, its reasoning needs to be clear and defensible. And legal and HR teams should be involved before development begins, not after a system is already built.
I’ll specifically defend the last point. We had a promising concept involving driver audio analysis, which is currently on hold pending consent and privacy review. Pausing before development is simple, but unwinding a system once it’s deployed is costly, especially when people are attached to it. That attachment complicates discussions rather than simplifying them.
As more companies move generative AI, RAG, and real-time analytics beyond the pilot stage, what lessons from your own work would you share with leaders trying to make AI useful, reliable, and scalable in the real world?
Start where a human already performs the task. This provides a baseline, an actual cost, and someone who can quickly spot mistakes in the output. Greenfield use cases without existing processes are typically where pilots get praised at first and then quietly put aside.
Most RAG failures stem from retrieval issues rather than model errors. Teams often spend months changing models when the real issues are with chunking, metadata, or outdated indexes. Assess retrieval independently of generation to avoid blind debugging.
Instrument your system from the start. You can’t improve what you haven’t logged, and adding observability after launch is much more costly than expected. Allocate resources for often-overlooked tasks: evaluation harnesses, drift detection, on-call support, and fallback mechanisms when the model is down. Remember, the demo represents only a minor part of the entire system.
Set clear kill criteria before starting. Determining the outcome that would make you halt is the most cost-effective discipline, yet almost no one practices it.