In legal review, the real risk is not the document AI flags. It is the one it quietly misses.
A polished AI demo can feel a lot like direct examination. The facts are favorable. The questions are friendly. The witness has been prepared. Everyone in the room gets to the answer they expected.
Litigation does not work that way. Litigation is closer to cross-examination. The story gets tested. The assumptions get challenged. The inconvenient details start to matter.
That is where document review becomes difficult. Custodians use strange file names. Attachments hide the important material. Privilege appears in places no one expected. Duplicates multiply. Email threads point in different directions. Someone, inevitably, saved the key spreadsheet in a folder called Old Stuff.
So the question for legal teams is not whether AI can sound smart in a demo. It is whether AI can help find the documents that matter when the data is messy, the stakes are real, and someone may later ask exactly how the review was done.
That question matters across litigation ESI review. Subpoena response makes it especially clear because the request is concrete, the timeline is unforgiving, and the cost of a missed responsive document is easier to see. A plausible answer is a useful start. It is not proof.
A demo proves very little
Most AI evaluations begin with a few impressive examples. The system finds a relevant email. It summarizes a request. It highlights the right paragraph. Maybe it identifies a pattern that would have taken a reviewer longer to spot. Someone in the room says, quite reasonably, that the result looks good.
The problem is not that the result is fake. The problem is that it is incomplete as evidence. A few strong examples show that the system can perform well under favorable conditions. They do not show that it will hold up across a full review population, with mixed file types, uneven metadata, long email threads, inconsistent custodian behavior, and documents that require judgment rather than keyword matching.
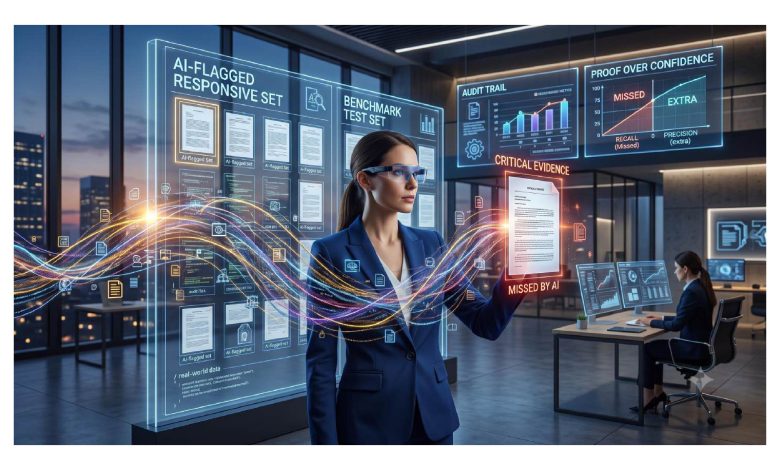
Before AI is trusted inside a real review workflow, legal teams need something more demanding than a demonstration. They need a known answer test set. That means a representative group of documents that attorneys or qualified reviewers have already reviewed and coded. The set should include obvious responsive documents, obvious nonresponsive documents, close calls, privileged material, attachments, duplicates, odd file types, and the kind of awkward documents that tend to create late nights and second opinions.
That collection becomes the benchmark. Once you have it, you can ask a meaningful question: when the AI is tested against documents where the right answer is already known, how well does it perform? Without that baseline, the team is not really measuring accuracy. It is measuring how persuasive the demo felt.
Accuracy is the wrong word until it is defined
When someone says an AI review tool is 92 percent accurate, the next question should be simple: accurate at what?
In document review, two very different issues often get collapsed into one friendly number. One is whether the documents the AI identifies as responsive are actually responsive. The other is whether the AI found the responsive documents it was supposed to find in the first place.
Those may sound like technical distinctions, but they are practical legal distinctions. Precision tells you whether the system is filling the review queue with noise. Recall tells you whether the system is missing documents that matter. Poor precision creates cost and delay. Poor recall creates risk.
That is why blended accuracy scores can be misleading. A single score may look impressive while hiding the weakness the legal team most needs to understand. A system might be very good at identifying obvious responsive material but weaker on attachments, spreadsheets, older custodian data, or documents that require context from a larger family. Those weaknesses matter.
The better question is not, What is your AI accuracy? The better question is, What does the system miss, how often does it miss it, and what controls exist when the stakes require a tighter standard?
The missed document is the one that changes the conversation
False positives are annoying. They are the documents the AI flags that turn out not to matter. They increase review volume, slow the team down, and drive up cost.
False negatives are different. A false negative is a document the AI missed that should have been reviewed or produced. That is the one that creates the more serious problem because no one is looking at it. It sits outside the review set until the other side finds it, a regulator asks about it, or the facts change and the missing document becomes important.
The absence of a result is not the same thing as proof that nothing exists. Legal teams know this instinctively, but AI can make the issue easier to overlook because the output often arrives with confidence. A clean answer can create the illusion of a complete process.
Every matter has its own risk profile. A routine third-party subpoena is not the same as a government investigation. A narrow employment dispute is not the same as bet-the-company litigation. Before AI is used in production work, the legal team should decide what level of missed-document risk is acceptable for the matter at hand. We assume it is fine is not a risk standard.
If testing shows that the AI struggles with certain custodians, file types, date ranges, terms, attachments, or document families, that does not make the system useless. It means the system needs supervision. It may be highly valuable as an assistant while still being inappropriate as an autonomous reviewer. Those are not the same thing.
Ask how the system was tested, not just what it can do
A stronger evaluation starts with less theater and better questions. What was the system tested against? If the test set was clean, narrow, or handpicked, the result tells you very little about how the tool will perform on real legal data.
Was there a known answer benchmark? If no one knew the right answer before the AI ran, then the team cannot really know how well the AI performed. It can only decide whether the output looked plausible.
Are precision and recall reported separately? If everything is rolled into one score, ask what that score is hiding. In legal review, the difference between extra noise and missed evidence is not academic.
What kinds of documents does the system miss? Every system has weak spots. Serious vendors should be able to talk about them directly. The answer will tell you a lot about whether you are dealing with a tool that has been tested in the real world or a story that has been polished for the room.
Can the system explain why a document was included or excluded? A black box answer may be interesting, but it is not especially useful when a partner, client, regulator, or judge asks what happened.
Where does attorney review occur, and what happens when confidence is low? Human review should not be an ornamental phrase added near the end of a workflow diagram. It should be a control point that is visible, configurable, and auditable.
And finally, is there an audit trail? If the team cannot reconstruct what the AI did, what the human reviewed, who approved the decision, and what changed along the way, then it does not have defensibility. It has hope. Hope is a poor review protocol.
Beware of demo theater
Some AI tools are excellent at performing in the conference room. They give confident answers, produce clean summaries, and make the future feel easier than the present. That has value, but it is not the same as readiness for legal review.
The real test is quieter and less flattering. Can the system survive repetitive, high-stakes work across messy data? Can it preserve context across document families and email threads? Can it separate responsiveness from privilege? Can it escalate uncertainty instead of burying it? Can it show what happened after the fact without everyone in the room holding their breath?
That is what legal professionals should want from AI. Not magic. Not swagger. Not a chatbot wearing a tie. They should want a system that can be tested, supervised, challenged, and defended.
Good legal AI should be boring to audit
The future of AI in litigation will not be decided by whether a model sounds like a seasoned litigator. It will be decided by whether the legal team can trust, explain, and defend the process around it.
That means real benchmarks, separate measures for precision and recall, matter-specific risk thresholds, attorney approval points, context-aware escalation, and complete audit trails. None of that sounds as exciting as an AI that answers questions in seconds. It is also exactly what makes the technology usable in legal work.
So the next time someone shows you an AI tool that finds documents, ask the question that actually matters: can it prove, with repeatable evidence, that it finds the right documents, and can your team defend how it got there?
Because in legal AI, confidence is not the standard. Proof is.