Organizations are moving quickly to put artificial intelligence to work. AI assistants are drafting communications, copilots are helping teams analyze information, and autonomous agents are beginning to execute tasks that once required direct human involvement.
Much of this adoption is happening one employee, department and use case at a time. A sales team creates an agent to support prospecting. Operations builds an assistant for reporting. A manager connects an AI tool to internal documents and uses it to generate training materials.
Individually, these projects can deliver real value. Collectively, they can create an operational environment that few organizations are prepared to manage.
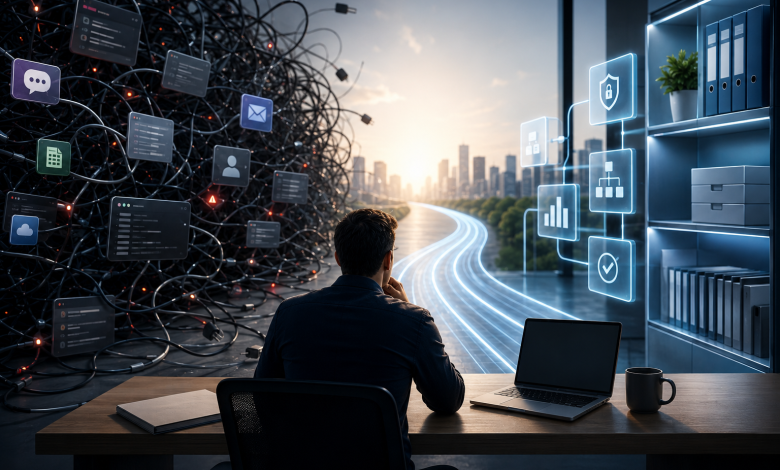
The result is a new form of technical debt. It is not necessarily buried in outdated code or aging infrastructure. It lives in undocumented prompts, disconnected workflows, overlapping subscriptions, unmonitored integrations and business processes that depend on AI configurations understood by only a handful of people.
Unless organizations address that debt early, today’s useful experiments could become tomorrow’s shadow IT problem.
AI Sprawl Begins with Good Intentions
Traditional shadow IT grew because employees could acquire technology faster than centralized IT teams could evaluate and deploy it. AI is following a similar path, but at a much faster pace.
An employee no longer needs to purchase and install a major software platform to change how work gets done. A subscription, a few prompts and access to several applications may be enough to create an AI-enabled workflow that influences customer communications, reporting, procurement or compliance.
The workflow may operate effectively for months without attracting much attention. Problems emerge when the person who created it leaves, the underlying model changes, an integration breaks or another department builds a separate version of the same process.
At that point, the organization may struggle to answer basic questions. Who owns the workflow? What information can it access? Which model is it using? How is its output evaluated? What happens when the technology or business requirement changes?
These questions become more consequential as organizations move beyond assistants that summarize information and toward agents that can initiate actions.
The OWASP Top 10 for Large Language Model Applications identifies excessive agency and overreliance among the risks organizations should consider when deploying AI applications. Giving an AI system access to tools and data can greatly expand its usefulness, but it also increases the importance of controlling what the system is allowed to do and verifying the results it produces.
Stop Building AI Around Individual Enthusiasts
Many AI programs begin with a technically capable employee who sees an opportunity and builds something useful. That person often becomes the unofficial owner of the organization’s prompts, assistants, integrations and internal knowledge resources.
This approach works during experimentation, but does not scale well.
A centralized company chatbot offers a useful example. An organization may create a custom assistant, load it with internal documents and position it as a source of company knowledge. Someone must then decide which information belongs in it, keep that information current, manage access and respond when employees need specialized data that was not included.
The organization has not eliminated knowledge management work. It has concentrated work around a new system and, frequently, a single person or small team.
A more durable approach is to build reusable frameworks that employees can configure around their own authorized systems. The organization defines the task, required safeguards, approved connections and expected output. Each employee then connects the framework to the applications and information they are already permitted to use.
This preserves consistency without forcing every employee into an identical knowledge environment. It also prevents the central AI team from becoming the curator of every document, workflow and departmental exception across the company.
The distinction matters. A reusable AI capability should include more than instructions telling a model what to do. It should also guide the user through what must be connected, what information is required, which permissions apply and how the completed workflow will be evaluated.
Without those foundations, organizations accumulate isolated AI tools that appear standardized on the surface but operate differently underneath.
Treat AI as Operational Architecture
Organizations often discuss AI governance as a policy exercise. They define acceptable use, prohibit certain data from being entered into public tools and create review processes for new applications.
Those controls are necessary, but policy alone does not reveal how AI is changing daily operations. AI must be treated as part of the organization’s operational architecture. That means maintaining visibility into which tools are being used, who has access, what systems they connect to and which business processes depend on them.
The NIST AI Risk Management Framework organizes AI risk management around four functions: govern, map, measure and manage. That structure is useful because it frames governance as a continuing operational responsibility throughout the life of an AI system, not an approval that happens once before launch.
In practice, organizations need an inventory that covers more than approved AI vendors. They should understand the active workflows operating inside those tools.
A license may be assigned to one employee, but that employee could have created several agents, dwconnected multiple data sources and embedded AI-generated output into decisions made by other teams. Looking only at software licenses provides an incomplete picture of the organization’s exposure.
Governance should also account for adoption. Organizations need to know whether employees are using approved tools, how they are using them and whether valuable workflows are being shared beyond the people who created them.
Tracking adoption is not about rewarding employees for generating the largest possible number of prompts. It helps identify where AI is creating measurable value, where employees need additional training and where expensive capabilities are being assigned without a clear use case.
Model Selection Is Becoming a Business Skill
AI adoption introduces a cost-management challenge that many organizations underestimate. Different models can carry different costs, speeds and levels of capability, even when they are accessed through the same application.
Using the most capable model for every task may seem like the safest approach. It can also waste resources and make successful pilots unnecessarily expensive to scale.
A complex planning exercise may require a model with stronger reasoning capabilities. Drafting routine communications, classifying information or executing a clearly defined step may not.
Employees therefore need to understand how to match the model to the work. This emerging discipline is sometimes described as token economics: understanding how model selection, context, prompts and repeated calls affect the cost of an AI-enabled process.
The organization can reduce some of that burden through design. Reusable workflows can default to the appropriate model for a particular task, establish limits on context and route higher-cost requests through additional review.
This makes cost control part of the architecture rather than expecting every employee to become an expert in model pricing.
It also encourages organizations to evaluate AI investments based on outcomes. Employees who demonstrate useful, repeatable applications may need access to more advanced capabilities. Others may need training before additional resources will produce meaningful value.
AI governance should support that progression. A system that treats every user and use case identically will either restrict valuable experimentation or spend heavily without knowing what the organization is receiving in return.
Access Should Follow the User, Not the AI
One of the most important design principles for enterprise AI is also one of the simplest: an AI system should not gain access to information merely because it can technically connect to it.
The system should operate within the permissions of the person and application using it.
There is rarely a good reason to expose an AI assistant to an entire enterprise data environment when the task requires only a narrow subset of information. Application-specific interfaces can provide the system with exactly what it needs while preventing it from reaching unrelated records.
This is particularly important in healthcare, where operational workflows may involve vendor information, facility access, compliance records, procurement activity and sensitive business data.
An AI assistant helping one employee review vendor activity should not automatically inherit access to every facility, customer or database available somewhere within the organization. Its permissions should reflect the user’s role, the specific task and the minimum data required to complete it.
CISA’s guidance on securing AI data similarly emphasizes access controls, data integrity and the protection of information used by AI systems. These controls affect more than confidentiality. Poor-quality, manipulated or improperly governed data can also undermine the reliability of the system’s output.
Narrow access creates additional engineering work at the beginning of an AI initiative. It prevents much more difficult remediation once an agent has become embedded in operational processes.
An AI Answer Is Not Evidence
Organizations also need a reliable way to determine whether an AI-generated answer is correct.
This sounds obvious, but many AI applications are deployed without a meaningful validation mechanism. The interface produces a polished response, the information appears plausible and the user moves on.
That may be acceptable when brainstorming a presentation title. It is not acceptable when the system is reporting compliance activity, summarizing operational performance or informing a business decision.
Consider an AI assistant asked to report how many representatives from a particular vendor visited a facility during the previous week. The assistant may respond that eight visits occurred and provide a convincing summary. The underlying system of record may show 12.
A strong architecture does not simply display the first answer. It compares the model’s response with the structured data returned by the source system, scores the result and reruns or flags the response when the two do not align.
Over time, that verification process creates a record of how accurately the application is performing. It also helps teams identify whether problems originate in the prompt, the model, the integration or the source data.
This type of continuous validation is essential as AI becomes part of reporting. Dashboards and traditional reports rely on defined queries and data structures. A conversational interface introduces another interpretive layer between the question and the result.
The convenience of asking a question in natural language does not remove the need to prove that the answer is right.
Build for Change from the Beginning
Every major component of today’s AI environment will change. Models will improve, pricing structures will shift, vendors will introduce new capabilities and regulators will clarify their expectations.
Business requirements will change as well. A workflow designed for one department may expand across the company, connect to additional systems or begin influencing decisions that were not part of its original purpose.
Organizations should assume that AI workflows will need to move between models, data sources and applications. Architectures that tightly bind a process to one vendor or one employee’s setup will make every future change more expensive.
Interoperability does not require pretending that all models and platforms are interchangeable. It means separating the underlying business process from the technology currently performing it.
The organization should be able to document what the workflow does, what information it requires, which actions it may take and how success is measured. That documentation becomes the stable layer even as the tools around it evolve.
This is how organizations prevent experimentation from hardening into technical debt.
The Real AI Advantage Is Operational Discipline
The organizations that gain the most from AI will not necessarily be those that deploy the largest number of tools or agents. They will be the ones that can turn successful experiments into repeatable, governed business capabilities.
That requires visibility into adoption, reusable implementation frameworks, controlled access, deliberate model selection and continuous verification of the output.
It also requires a shift in how leaders think about AI. These systems are becoming active participants in how work moves through the organization. They connect applications, interpret information and increasingly initiate the next step in a process.
Once AI reaches that point, it can no longer be managed as an optional productivity tool sitting outside the organization’s core architecture.