Enterprise AI has become remarkably easy to demonstrate. Give a capable model a narrow task, a curated set of documents, and a clean interface, and a team can produce something impressive in weeks. It can summarize a case, recommend an action, or complete a workflow.
Production introduces a much more complex operating environment, where customer records may conflict, permissions can change, APIs can fail, and data can quickly become outdated. The same customer may also appear differently across multiple systems, leaving AI to make decisions with an incomplete or inconsistent view. In that environment, model performance alone doesn’t determine whether an outcome can be trusted. Reliability depends on the quality of the data, context, and controls surrounding the model.
That gap helps explain why investment continues to outpace enterprise-wide scale. A recent Gartner survey found that only 22% of organizations have successfully scaled AI across multiple business units or adopted an AI-first approach, even as 85% of functional leaders plan to increase AI spending in 2026.
The next enterprise AI challenge is operational. Companies need an architecture that can supply the right context, constrain authority, explain decisions, and recover when something goes wrong. A pilot proves that a model can perform a task. Production proves whether the business can depend on the system around it.
A Pilot Proves Capability. Production Tests Context.
Pilots simplify the environment around a model. Teams work with a defined data set, known users, a narrow use case, and a limited set of actions. That answers an important early question: can the AI perform the task?
Production asks a harder question: can the system perform that task reliably while the context around it keeps changing?
Consider a customer service agent that can issue credits or change an account. During a pilot, it may work from carefully selected records. In production, the same customer might have an active subscription under one email address, a service case tied to another, an outdated preference in a marketing platform, and a loyalty account in a separate system.
The agent may follow its instructions perfectly and still make the wrong call. That is not primarily a model failure. It is a context failure.
McKinsey research makes a related point: enterprises need governed, reusable data foundations that connect structured and unstructured information so AI systems can treat what they use as reliable business context. That foundation becomes operationally useful only when the business can connect the context to the right customer, at the right moment, under the right controls.
Customer Identity Is Production Infrastructure
Customer identity has traditionally been treated as an analytics, marketing, or data-quality concern. Agents make it part of production infrastructure because the system may use customer information to act before a person reviews the result.
A customer can appear under different emails, devices, loyalty accounts, transactions, and service records. Leave those records fragmented and an agent works from a partial history. Combine them too aggressively and it may use information that belongs to two different people.
Both failure modes matter more as agents gain authority. They can lead to redundant offers, incorrect retention decisions, or account changes based on mismatched information. Identity resolution therefore needs the same discipline as any other production service: known inputs, measurable quality, confidence signals, monitoring, and a way to correct errors without forcing every downstream application to reconstruct the customer.
Context Has to Be Alive
Even a clean customer profile loses value when it becomes stale. A purchase, cancellation, support ticket, preference change, or transition from anonymous browsing to an authenticated session can change what the system should do next.
Freshness is part of decision quality. A profile that was accurate last week can produce a bad decision today if the system missed the event that changed the customer’s circumstances.
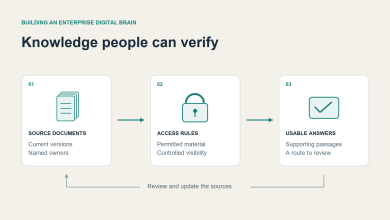
This is why context engineering matters. Anthropic describes it as the process of curating and maintaining the information available to an AI system as it operates, including instructions, tools, external data, and message history. In an enterprise, that context also has to include resolved identity, permissions, business rules, prior interactions, and current system state.
The goal is not to give an agent every piece of available data. More context is not automatically better context. The goal is to supply the minimum trusted context needed for the decision, keep it current, and make its provenance clear.
Governance Has to Travel With the Decision
Production AI reaches into business tools, customer records, and operational workflows. Governance cannot live only in a review committee or policy document. It has to be enforced where the decision is made and where the action is taken.
NIST’s AI Risk Management Framework asks organizations to address trustworthiness across the design, development, deployment, and evaluation of AI systems. Its generative AI profile extends that thinking to risks specific to generative systems.
For an enterprise agent, that principle becomes concrete: What data can it access? Which actions can it take? When is human approval required? What happens when a policy check fails, the evidence conflicts, or confidence falls below an acceptable threshold?
Prompts and instructions can influence behavior, but they are not authority controls. Permissions, transaction limits, approval gates, and policy enforcement determine what the system can actually do. The agent should receive only the access and context required for the task.
Observability Must Reach the Decision
Traditional observability tells teams whether a system is healthy: latency, errors, resource use, and successful completion. AI systems require another layer. A workflow can complete without a technical error and still produce the wrong outcome.
Teams need decision observability. They should be able to reconstruct what the system knew, which sources it used, what policy and model versions were active, what action it selected, and what changed downstream. That trail must be useful to engineers, risk teams, and business owners, not just stored as an opaque log.
Without that visibility, a company cannot distinguish a model problem from a context, identity, policy, or integration problem. It also cannot reliably prevent the same failure from recurring.
Reliability Includes Recovery
No production system works perfectly, and agents introduce additional failure modes as they make dynamic decisions across multiple systems. An API can fail halfway through a workflow, context can change after planning begins, or an action can succeed in one system and fail in another.
Companies should decide in advance how those situations will be handled. Systems need idempotent retries, checkpoints, clear pause and escalation paths, and reversible actions where the underlying operation allows them. High-impact actions may also need a dry-run mode or explicit approval.
OWASP’s guidance for agentic applications recommends reversible transactions or dry-run modes for state-changing actions, along with explicit controls for operations with larger potential impact. Autonomy becomes easier to trust when recovery is part of the design, not an incident response improvisation.
Build a Shared Context Layer Before Scaling Agents
AI initiatives can recreate the fragmentation enterprises have spent years trying to solve. A support agent builds one retrieval layer, while marketing and commerce build their own customer views. Soon each system has a different definition of the same person, different permissions, and different decision history.
That pattern increases cost and operational risk because every new agent has to solve the same identity, access, governance, and context problems. A stronger architecture treats trusted context as shared infrastructure. Each application gets the information it needs, subject to its own authority boundaries, while the enterprise maintains a common way to resolve identity, apply policy, observe decisions, and learn from outcomes.
Models and interfaces will continue to change. The more durable layer is the business context around them: identity, history, current signals, permissions, rules, decision records, and feedback. Building that layer once gives companies more freedom to adopt new models without rebuilding the operating foundation every time.
Production Is Where AI Earns Trust
Moving from a compelling demo to a dependable enterprise system requires production readiness to be designed from the start. Teams need to test context accuracy, keep information current, enforce authority boundaries, record how decisions happen, and build workflows that can recover safely.
The key question is no longer whether AI can generate a plausible answer or complete a task in a controlled environment. It is whether the business can understand, govern, and depend on the decision when real customers, real systems, and real consequences are involved.