Large language models have a goldfish problem. The industry has poured billions into models that can reason over petabytes of training data, but in practice, their working memory is tightly constrained.
Even the most expansive context windows tap out after about an hour-long video call. RAG (Retrieval-Augmented Generation) and vector databases help, but they often compress and fragment information, losing the temporal connections that make up real-world context.
Graphon Labs wants to give AI a permanent, searchable memory.
This week, the applied AI lab announced a $35 million Series A led by RRE Ventures, with backing from HP, Energy Impact Partners, Hitachi Ventures, and Gaia VC. The round comes less than six months after the company’s $8.3 million seed debut, bringing its total funding to $43.3 million.
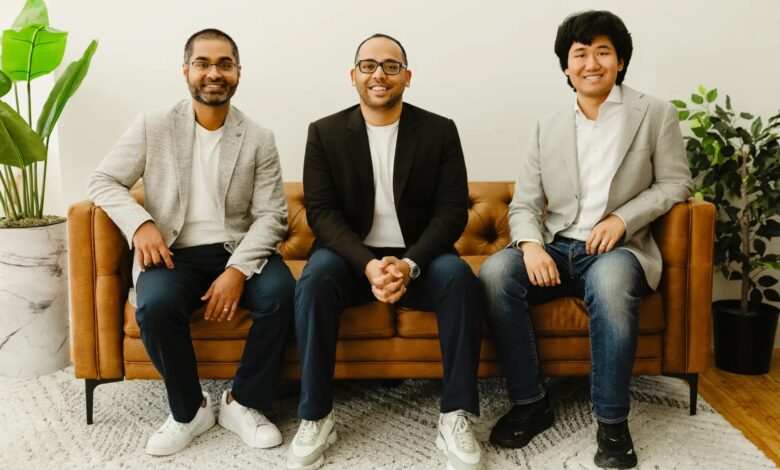
Founded by a team of researchers and engineers out of Amazon, Meta, Google, Apple, and NVIDIA, Graphon Labs is building what it calls “Persistent Intelligence.” The goal is to allow AI agents to continuously access, understand, and build upon a limitless timeline of documents, photos, videos, emails, and Slack messages.
“In a world where we are moving to AI using computers, we need to fundamentally rethink how computers access data to pre-fill their context windows,” said Arbaaz Khan, founder and CEO of Graphon Labs. “The old way, using vector search, is like searching through the pages of a torn-up book. We take those pages and turn them into a connected map, unlocking seamless memory search.”
The startup’s secret sauce lies in its namesake: graphons. Originally developed as a branch of mathematics used to analyze massive networks and coordinate robotic drone swarms, the founders adapted the framework during their PhDs to map complex, multimodal data. Instead of just pulling up a loosely related text chunk, Graphon’s architecture reads what happens inside each data point and maps the people, places, and moments across all of them. It then traces every AI-generated answer back to the exact frame, page, or timestamp it originated from.
In practice, this means a consumer could ask their smartphone to “show me the moment a boat passes on the water in my videos,” and the underlying memory system would parse thousands of localized files to pull the exact clip. On the enterprise side, a quality assurance manager at a food manufacturer could ask why unlabelled packages shipped, and the AI could scan hundreds of thousands of line-camera clips across multiple factories to return a root-cause timeline, from footage of blank bottles to a label approval that stalled out in an inbox.
The pitch is already landing with major enterprises. Graphon Labs is currently deployed with HP, Hitachi Rail, and the San Francisco 49ers.
“From uncovering new sponsorship opportunities to empowering our teams, we’re excited to explore how Graphon Labs’ technology can help us gain a competitive edge,” said Costa Kladianos, EVP of Technology for the 49ers.
The lab is also bringing receipts to back up its tech. On LoCoMo and ConvoMem, two leading benchmarks for evaluating long-term AI context, Graphon scored 93.9% and 90.2% accuracy respectively, using over 50% fewer tokens than standard methods. On Cambridge’s multimodal ATM-Bench, Graphon sits at the top of the public leaderboard.
With the fresh capital, Graphon Labs is moving beyond bespoke enterprise deployments. The company is rolling out three core products: Graphon Enterprise for secure, governed corporate data; Graphon Developer, allowing builders to integrate this memory stack without starting from scratch; and Graphon On-Device Memory, a localized version designed to run persistently on phones, laptops, and wearables.
For Khan and his team, solving the memory bottleneck isn’t just an infrastructure play; it’s a required stepping stone for the industry’s broader ambitions. If AI agents are going to run continuously in the background of our lives and businesses, they have to remember what they did yesterday to learn for tomorrow.