The EU AI Act has made it harder for boards to speak about AI in the abstract. That is progress.
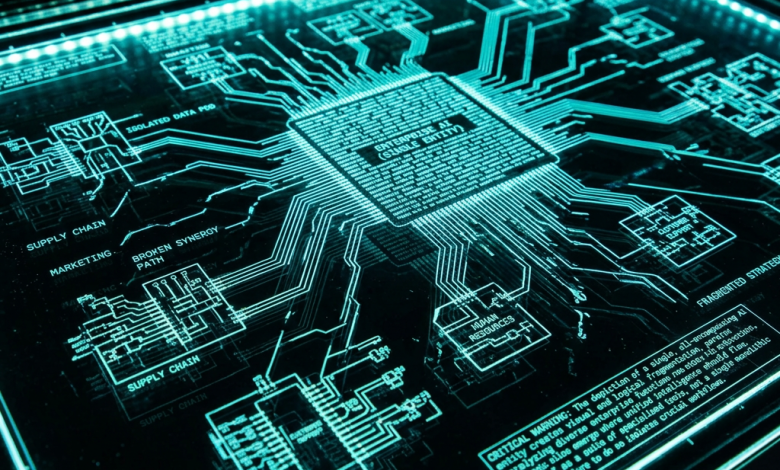
For too long, the boardroom question has been very generic: How do we govern AI? The more consequential question is: What kind of intelligence are we governing?
This distinction is now becoming decisive. MIT Project NANDA’s preliminary State of AI in Business 2025 study found that 95% of organizations in its sample saw no measurable profit-and-loss impact from their generative AI initiatives. The report did not blame regulation or model quality; it pointed to approach, brittle workflows, weak contextual learning and operational misfit.
I believe the deeper executive failure is a governance mismatch.
Enterprises still file all of it under one heading. Consumer chatbots, private automation, AI-enabled public services and sovereign defence systems land in the same conversation, and it all becomes one shapeless argument about “AI compliance”. They don’t carry the same risk. They differ in nearly everything that matters: purpose, who gets hurt when they fail, how sensitive the data is, how much autonomy anyone should be handing over.
So I’ve stopped using the label on its own. I look at four environments: consumer AI, private enterprise AI, government-to-citizen AI, and military or national-security AI. Nearly every governance argument I watch go round in circles is one where those four got collapsed into one.
The EU AI Act exposes that AI is not a single entity
Article 50 of the EU AI Act, which became applicable on August 2, 2026, intends to produce consistent and proportionate transparency.
While its objective is straightforward, ensuring people know when they are interacting with AI or encountering synthetic content, the compliance obligations vary significantly depending on the system’s purpose.
For instance, providers of interactive tools must ensure immediate user awareness, while creators of generative AI are required to embed machine-readable watermarks. Meanwhile, downstream deployers face distinct disclosure mandates for deepfakes, emotion tracking, biometric profiling, and public-interest text.
One article, four different answers. “AI transparency” already doesn’t mean the same thing twice. For consumer AI it’s about what somebody sees on a screen. For enterprise AI it goes a great deal deeper: a bank running fraud detection needs to know what data the system reaches, which model acts on it, what it’s permitted to do, and who picks up the phone when it’s wrong.
The strongest evidence that AI isn’t one thing arrived a week before Article 50, and I don’t think enough people noticed. The Digital Omnibus came into force on 27 July 2026. It pushed high-risk obligations for standalone Annex III systems out to 2 December 2027, and AI in regulated products to August 2028, while leaving Article 50 and Article 4 literacy duty exactly where they were.
Look at what that means. Europe examined its own law, decided the pieces couldn’t run on one clock, and split the timetable by what the systems do. If you’ve spent two years building one AI compliance program, your regulator has just told you the premise was wrong. That’s information, not a reprieve.
For enterprise AI, transparency must reach much further beneath the surface.
Article 2 reinforces the same point at the level of scope. The EU AI Act applies in defined circumstances to providers, deployers, manufacturers, importers and affected persons, even to those outside the EU, but with AI systems creating output in the Union. The regulation excludes military, defense, national security purposes, R&D, and personal non-professional activities.
In other words, even the law does not treat AI as one undifferentiated object.
The Act brings the debate back to data and people
The most mature reading of the AI Act begins not with the model, but with the data.
For high-risk systems, Article 10 covers data origin, collection, preparation, suitability, representativeness, bias, gaps and the geographical or functional context of use. Article 26 places responsibilities on deployers, including appropriate controls, competent human oversight, relevant input data, monitoring and log retention.
This is why enterprise AI cannot be governed as an extension of chatbot policy.
Enterprise AI strategy must begin with data strategy: identifying data assets, classifying them, understanding lineage and metadata, defining data contracts, determining where information resides and controlling how it can be used.
Human oversight must be equally specific. As I see it, enterprise autonomy should be understood through the relationship between humans, systems and permissions: human in the loop, on the loop or over the loop, depending on the use case.
Accountability now travels across the AI value chain
The Act’s definitions are not legal housekeeping. They describe the commercial relationships through which responsibility will travel.
Article 3 distinguishes the provider that develops or places a system on the market from the deployer that uses it under its authority, alongside importers, distributors and other operators. It also makes “intended purpose” central: the context and conditions in which a system is represented as being designed to operate.
That matters because enterprise AI is rarely supplied by one party. An application may sit above a hyperscaler, call a frontier model, incorporate an open model, use proprietary data and trigger tools across several systems. That produces an AI supply chain.
For high-risk systems, Article 25 makes the consequences explicit. A deployer, importer, distributor or third party may become the provider if it rebrands or substantially modifies a system or changes its intended purpose so that it becomes high-risk. It also anticipates written agreements covering the information, technical access and assistance required for compliance.
This is where regulation and model strategy converge. Contracts will increasingly have to specify where responsibilities change hands when data is routed through third-party models, infrastructure and services, who controls the model, where data travels and who can change the system.
When an AI system fails, the enterprise deploying it needs clear accountability, not a supply chain of global providers passing responsibility from one to another.
Rent Intelligence or own it? Go Glocal
Frontier models are valuable for broad reasoning. Smaller, open or fine-tuned models can be better where enterprises need predictable cost, local processing, specialized performance or tighter data control. Some workloads require private infrastructure; others can safely use hosted services.
So, when the decision is to “how much intelligence to rent, operate or own,” the right answer is not ideological purity but a governed portfolio.
The practical strategy is “glocalization”: global architecture and governance principles, with controls configured for the local market.
That means combining baseline capabilities running locally, approved open models hosted in regions that meet enterprise requirements, and frontier models available for selected use cases through a controlled harness.
In practice, a glocal model-routing strategy for an EU enterprise can use globally capable foundation models where the risk is low, route sensitive workloads to regional or self-hosted models where data, security or regulatory requirements call for greater control, use smaller local models for high-volume bounded tasks and reserve frontier models for work that genuinely requires them.
The architecture stays global, but model choice, data routing, approvals, transparency and evidence requirements can vary according to the use case, risk, regulatory obligations and local requirements.
EU AI Act makes Glocalization even more important
The EU may provide a common framework, but enterprises still operate across 27 member states, each with its own national nuances. The UK is different again, having taken a different path from the EU. Rather than creating one comprehensive AI statute equivalent to the EU AI Act, it has largely relied on existing regulators and sector-specific frameworks to address AI within their domains.
But regulatory divergence does not mean commercial separation.
A UK company operating in European markets, providing technology into the EU or participating in an AI supply chain that reaches European users, needs to understand where EU requirements may apply.
“Where is my company headquartered?” is irrelevant; what matters is “Where does my intelligence operate, and where are its outputs used?”
For multinational organizations, this creates what I call the interaction between three sets of laws: the laws of physics, the laws of economics and the laws of the land.
Physics determines where processing can happen efficiently, based on factors such as latency and infrastructure. Economics determines whether an architecture makes commercial sense. Regulation determines what is permitted in each jurisdiction.
A good AI architecture must accommodate those differences without fragmenting the enterprise. It should enable the enterprise to establish common controls around data, identity, security, observability and accountability while making different decisions about models, infrastructure and processing according to jurisdiction and workload.
This is why global enterprises need a glocal AI operating model: common governance principles globally, with implementation that adapts locally. It also gives a more useful conception of sovereignty than pretending any major economy can build an entirely self-contained AI stack.
AI economics must become part of governance
US executives may discuss AI through the language of return on investment, while European leaders face a sharper debate about data protection and sovereignty.
In practice, these are becoming the same decision because AI is changing software economics. Traditional software business models assumed that, once a product was built, the marginal cost of serving another user approached zero.
AI reintroduces variable cost through inference, tokens, tools, memory, orchestration and repeated execution. Every model choice is therefore also a financial-governance choice.
The right metric is not cost per token or license. It is the cost per completed, compliant business outcome. That calculation should include cycle-time reduction, error avoidance, risk reduction and revenue impact, alongside human oversight, monitoring, evidence and remediation.
The cheapest model is not always the least expensive to operate. Once accuracy, human oversight, compliance controls, and data risk are included, a more governed model often delivers greater business value and lower operational cost.
From pilot theater to governed intelligence
I believe the organizations that treat the EU AI Act as an architecture reset opportunity rather than a legal obstacle will ultimately move faster.
For leaders in the UK, the US and Europe, the strategic imperative is to govern AI according to its purpose, data, output and economics, not as a single undifferentiated technology.
In practice, that means to classify the use before selecting the model; establish data and accountability before scaling; preserve model choice rather than hard-wiring dependence; and make economics, contracts and controls part of the architecture from the beginning. We hold these together through what we call the XDO blueprint, though the label matters much less than the habit.
Ask five harder questions: What intelligence are you using? What data does it touch? Where does that data and intelligence run? Who is accountable for the outcome? And what measurable business value justifies it?
Answer those honestly and most of the fog lifts.