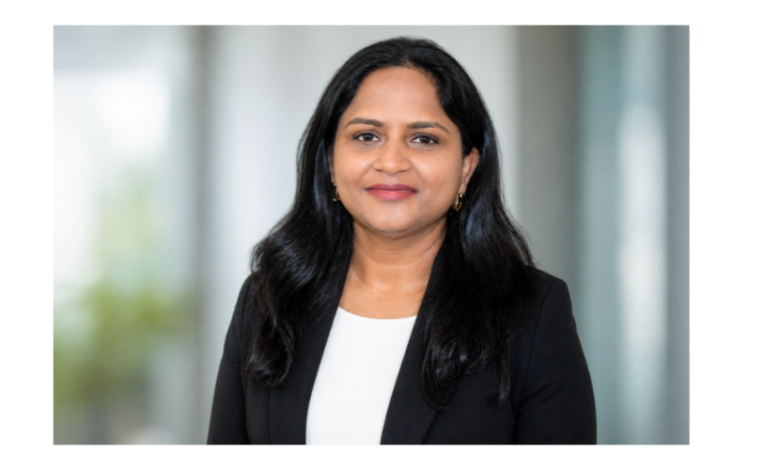
Jyothsna Salla has spent more than fourteen years in enterprise technology, where she is responsible for the identity platform, including the company’s VPN. Before that, she held technical leadership roles on Azure environments and cloud adoption.
Her work sits at an uncomfortable intersection, the identity layer has to be invisible to legitimate users and immovable to everyone else, and the people attacking it have become faster and cheaper to run. In this conversation, she talks about what it actually takes to federate applications without breaking the business, what password spray looks like from the defender’s console, and why she thinks the arrival of AI agents inside the enterprise is really an identity problem wearing a different name.
1. You run identity for a company where a bad change on your platform means thousands of people can’t log in on a Monday morning. Before we get into AI or attackers, what does ordinary stewardship of that system look like? How do you decide what gets changed, when, and who has to agree first?
I think of the identity platform as something I’m looking after rather than something I own. Nothing goes in without a reason, and nothing goes in blind.
Every change starts with analysis. I look at how the current setup works, what the change actually touches, and what it does to future operations. A sign-on policy change sounds small on paper, but it might affect how a VPN client authenticates, how a service account behaves, or how a contractor in a different domain gets in. So I map that out first.
Then I test it in a lower environment. We have a preview tenant that mirrors production, and the change runs there before anyone sees it in the real system. If it’s an authentication policy, I pilot it with a small group before rolling it out wider.
Anything that touches authentication goes through our information security team. I work closely with them, and I don’t push a policy change on my own. We check it against current industry best practices, whether it’s phishing-resistant MFA, session lifetimes, or device trust. They see things I don’t, and I see the operational side they don’t, so the review goes both ways.
One thing I’ve learned to take seriously is how users will respond. If the sign-in experience is about to change, people need to hear about it before it happens. Otherwise, the help desk hears about it first, and users start looking for workarounds, which is how you end up less secure than before.
Once Information Security(Infosec) team and the change management reviewers have approved it, there’s a defined window, a rollback plan, and I watch the system logs closely afterward. On a normal week, the work is less dramatic than it sounds: reviewing policies, cleaning up unused apps and groups, checking admin role assignments, rotating certificates and API tokens before they expire. That routine is most of what stewardship is. The discipline is boring on purpose. When 3,500 people depend on the same front door, boring is the goal.
2. You led the Single Sign-On and federation rollout across more than 170 SaaS and enterprise applications using Okta. Walk me through how that actually unfolded. What did the first ten applications teach you that changed how you handled the next hundred and sixty, and which one fought you the hardest?
The first ten taught me that the integration itself is the easy part. Connecting an application to Okta over Security Assertion Markup Language(SAML) or OpenID Connect (OIDC) takes an afternoon. What costs you is everything you didn’t ask before you did it. Early on we had a few integrations that technically worked and still had to be redone, because we hadn’t thought about who was going to maintain them or how access was going to be granted six months later. That’s where the checklist came from, and it’s what made the next hundred and sixty go much more smoothly.
Now, before I touch anything, I want to understand the application itself. What is it actually for, what tech stack is it built on, and is it a SaaS product or something hosted inside the organization? Those answers tell me what the vendor supports, how much control we have over the login flow, and how much customization I should expect.
Then I look at the users. Is it internal employees only, or do external partners and contractors need to get in, or even customers? That changes everything downstream: which directory they live in, which domain they authenticate from, and how strict the access policies need to be.
Next is the protocol and the policy. Is this going to be SAML, OIDC, WS-Federation (WS-Fed), or something older that needs a workaround? What access policies apply, and does this application warrant a specific type of MFA, like a hardware key such as a YubiKey, versus a one-time code? A finance system and an internal wiki should not have the same sign-on policy, and deciding that up front is much easier than tightening it after people are used to the easy path.
Then there’s the question of how access actually gets assigned. Are we using Okta groups or Active Directory groups, and who owns membership in them? Does the application need automated user provisioning and deprovisioning through System for Cross-domain Identity Management (SCIM), or is manual assignment acceptable? Provisioning is where licensing comes in too. If every assigned user consumes a paid seat, the application owner needs to know that before we open the door to a large group.
And finally, the operational side. Who owns this application after go-live? What are they responsible for, and what do they need from me? If that isn’t clear, the integration quietly becomes my problem forever.
If you skip any of those steps, you get one of three outcomes: rework, operational overhead for the users or the application owner, or access that’s less secure than it should be. Usually more than one. Asking the questions first is slower for about a week and faster for the next five years.
3. I want to ask about a very plain-sounding line in your record: you created a separate domain for external users. Why wasn’t it enough to just give vendors and partners accounts in the main directory with tighter permissions? What risk were you designing against, and what did you have to give up to get the separation?
The honest answer is that “tighter permissions” is only as reliable as the data those permissions depend on, and in a large organization that data is always moving.
Let me give you the scenario I was designing against. Say employees, contractors, partners, and customers all live in the same identity tenant. Access to an internal application is controlled by a dynamic group, and membership in that group is driven by a profile attribute called Employee Type, with values like Full Time Employee (FTE), Contractor, and Customer. That is a perfectly normal design. Most companies have something like it.
Now imagine a sync job between HR and Active Directory misfires, or someone makes a data entry mistake, and a handful of customer accounts get their Employee Type flipped to FTE. Nobody changed a permission. Nobody approved anything. But the dynamic group picks up the new value, and overnight those external users are inside applications that were never meant to leave the building. That could be the design files for a product that hasn’t launched. It could be a dashboard with revenue and sales figures. It could be an internal document library.
That’s the nightmare. The exposure is silent, it’s caused by a data problem rather than a security decision, and by the time anyone notices, confidential information has already crossed the boundary of the organization. At that point you’re not dealing with an access issue anymore. You’re dealing with legal and contractual consequences, and possibly disclosure obligations.
Putting external users in their own domain means a mistake in HR data can’t turn into an unintended access grant. The boundary is structural, not attribute-based. One bad value in a profile field can’t bridge it, because the two populations don’t share a directory to begin with.
The rule I follow is simple: internal employees can see what partners and customers can see, but it never goes the other way. The downside of that asymmetry is small. The downside of getting it wrong in the other direction is very expensive.
4. Let’s talk about the attackers. Password spraying is one of the oldest tricks in the book, and it still works. What does a spray campaign look like from where you sit the signals, the cadence, the accounts they go after and what did you change in your sign-on policies or MFA posture the first time you saw one land?
Password spraying is still around because it’s cheap and it works. The attacker doesn’t need anything clever. They write a script that hits an exposed login or authentication API, feed it a list of usernames, and try a handful of common passwords against each one. Spray is the opposite of brute force: one or two passwords across thousands of accounts, instead of thousands of passwords against one account, so it slides under lockout thresholds.
The username list is the easy part for them. Corporate email addresses are not secret. Every time one of us signs up for a tech talk, a webinar, a newsletter, or a conference to keep our skills current, that address goes into another database, and sooner or later some of those databases leak. Attackers also know most companies follow a predictable format, so once they have a few real addresses, they can guess the rest.
The first time I saw one land, it showed up as a number before it showed up as anything else. We came in one morning, and threat events in the identity platform were up more than 200 percent overnight. That’s the first signal: a sudden jump in failed authentications that doesn’t match anything happening in the business. When I dug into the system log, the pattern was clear. One application was being hammered with login attempts using a mix of random and plausible usernames and a short rotating set of passwords. The attempts came from IP ranges we had no business with / were spread across many source addresses to avoid rate limits or deny access to those specific IP addresses.
What made the difference is that the application was behind Single Sign On (SSO). Instead of exposing its own login form, it redirected every attempt to the identity platform, which meant every failure was authenticated against our policies, blocked at Multi-Factor Authentication (MFA), and written to a single log where we could see the whole campaign at once. If that application had been managing its own passwords, I think there’s a real chance at least one of those attempts would have worked, and we might not have known for a long time.
That incident changed our posture in a few concrete ways. We removed SMS and voice calls as MFA options, because they’re no longer strong enough; SIM swapping and interception have made them a weak link. We cut the default session lifetime from 24 hours to 12. And we moved to requiring MFA on every new session when accessing applications, rather than letting a long-lived session carry people through. Each of those adds a small amount of friction for users, and we were upfront with them about why. A spray that gets a correct password and then hits a hard MFA wall is a spray that failed.
5. Every AI agent, copilot, and automation flow now needs credentials, scopes, and a way to be revoked, and most of them aren’t people. How do you think about non-human identities service accounts, agents, workflows that act on a user’s behalf and are the IAM tools we have built for humans the right fit?
The first thing I’d say is that non-human identities aren’t new. Service accounts, API keys, automation flows with stored credentials, shared break-glass accounts: those have been in every enterprise for twenty years. What’s new is the volume and the autonomy. An AI agent isn’t a scheduled job that runs the same query every night. It makes decisions, it chains actions across several systems, and it does it fast. So the old habits around service accounts, which mostly amounted to “create it, give it broad permissions, never rotate the password, forget who owns it,” are exactly the habits that get you hurt now.
My view is that an agent should be treated as a first-class identity in the directory, not as a secret buried in a config file. That means it has its own record, its own credentials, its own owner, its own policies, and its own entry in the logs, the same way an employee does. If I can’t answer “who is this agent, who approved it, what can it reach, and when does it expire” in one place, I don’t have control of it.
The second principle is delegation rather than impersonation. The dangerous pattern is giving an agent standing access to everything on the chance it needs it. The right pattern is a token exchange: a user authenticates normally, the agent exchanges that identity for a narrowly scoped, short-lived token that lets it act on that user’s behalf, and only within the scope that specific task requires. When the task ends, the token dies with it. The agent never holds the user’s credentials and never carries access it doesn’t need in that moment. That’s how agent-to-app and app-to-app connections stay inside the identity perimeter instead of becoming a parallel, unmanaged web of API keys.
Third is discovery and posture. In most organizations, nobody knows how many service accounts, tokens, and automation identities actually exist, let alone which ones have privileged access or haven’t been used in a year. You need tooling that continuously finds those identities across your environment, scores their risk, flags ones with no owner or stale credentials, and surfaces privileged access that should be reduced to zero standing privilege, meaning the access is granted just in time and taken back afterward.
Fourth is lifecycle and governance. Human identities have joiner-mover-leaver processes and periodic access reviews. Agents need the same thing. Someone owns it. It gets recertified. When the project ends, or the owner leaves, it’s deprovisioned, not orphaned. And the audit trail has to show not just that the agent did something, but which user it was acting for and why it had permission to do it.
The identity platforms are catching up fast, and the right capabilities are arriving. The real risk is organizational, not technical. If AI agents are rolled out by product teams faster than identity and security can bring them under governance, you end up repeating the shadow IT problem, except this time the shadow has credentials and initiative. I’d rather be slow and in control at the front door than fast and surprised later.
6. Plenty of organizations still treat IAM as an IT cost center. If you were in front of a CEO who sees identity as “the login page,” what would you tell them in two minutes about why it belongs on the risk register alongside revenue and reputation and what’s the one thing you’d want every application team to get right before they ship?
I’d agree with them: it is the login page, and that’s exactly the point. It’s the one piece of the company every employee, contractor, partner, and attacker passes through, and everything we value sits behind it: financial systems, product designs, customer data, source code, the VPN. When a company makes the news for a breach, the headline says “cyber attack,” but the details are almost always an identity story. A phished password, a service account nobody rotated, a former contractor whose access was never removed, an MFA prompt approved at midnight to make it stop buzzing. The attacker didn’t break in. They logged in. The cost of that shows up as regulatory exposure, legal consequences, and reputational damage, and all of it comes straight out of revenue.
Identity done well isn’t only defense. It’s how 3,500 people get into 170 applications on a Monday morning without calling the help desk, how a new hire is productive on day one and a leaver loses access the hour they walk out, and how we can approve a new SaaS tool or an AI agent in a week instead of a quarter because the access model already exists. Companies that treat identity as a cost center pay for it twice, once in friction and once in incidents. What I’d ask for isn’t a budget the size of a data center. It’s a seat in the room when the business decides what to build and buy, instead of being called in afterward to clean up.
The one thing for application teams: don’t build your own front door. Before anything ships, it should authenticate through the central identity platform over a standard protocol like SAML or OIDC, with access assigned through governed groups and MFA enforced by policy rather than by the application. Every team that writes its own login, stores its own passwords, or hands out its own API keys has created one more door we have to defend and one more place a leaver can keep a key. Get that single decision right and almost everything else in identity becomes manageable. Get it wrong, and nothing I do at the platform level can fully fix it.