Every few months, a new frontier model raises expectations for what AI can do. Their ability to reason, write software and tackle problems that once seemed out of reach continues to improve.
I get asked all the time whether specialized AI will eventually become unnecessary. My answer remains the same: specialized AI will hold its own, even as these new systems become more intelligent and efficient. This article explains why.
As adoption matures, organizations are asking different questions. What strategy should we take? Which models deserve our trust? How should we decide when a general-purpose model is enough and when a specialized one is the better choice?
Those questions have less to do with how capable today’s models have become and more to do with what they’re being asked to do.
The Value of a Well-Defined Objective
General-purpose models learn patterns that transfer across an extraordinary range of tasks. Specialized models are developed with a much narrower objective and refined until they perform that objective exceptionally well, both in terms of efficiency and accuracy. They’re optimized for different kinds of problems.
That distinction becomes difficult to ignore once AI begins supporting repetitive decisions that carry operational or financial consequences.
The rapid advancement of frontier models has understandably shifted attention toward general-purpose AI. Systems that can summarize documents, write software and reason across many domains create the impression that one model architecture can solve almost any business problem. In many cases, it can. The question is whether it’s the best tool for every task.
Most organizations are built on repeatable processes designed to produce consistent outcomes. Those processes drive revenue, reduce risk and create predictable results across the business. Where those processes can be standardized, organizations invest heavily in making them as efficient and reliable as possible.
Foundation models are indispensable when those workflows involve language, reasoning or other unstructured information. Outside those use cases, the tradeoffs start to change. Many operational workflows are built around structured inputs, clearly defined objectives and repeatable decisions.
In those environments, specialized machine learning models and well-designed software offer significant advantages.
The Difference is in the Data
Specialized AI models (supervised machine learning) are built to minimize error on a defined task. When the objective is precise and the model is trained on carefully curated examples, supervised learning can reach or exceed human performance on tasks such as detecting swimming pools in aerial imagery.
The more examples of “correct” results the model is provided with, the more perfectly the model can perform the task. There are important caveats:
Careful definitions are required. What qualifies as a swimming pool? Are hot tubs or temporary pools included? The training examples must represent “real world” usage.
Performance is limited by definitional precision, input data quality (e.g., image resolution) and training data set size. Training data can get expensive. For visual data, hundreds of thousands or even millions of curated examples can continue to improve performance.
Validation requires the same level of care. The model should be tested against a separate, representative set of examples it has never seen before. Only then can organizations judge whether it will perform reliably under real operating conditions. That upfront investment makes specialized AI best suited to tasks with durable, long-term value. Once developed, a supervised model can execute one or several well-defined tasks with considerable accuracy and efficiency.
Specialized AI in a Foundation Model World
General-purpose models are optimized to learn statistical patterns from large volumes of text and images. Their strength lies in versatility. They can summarize documents, generate code, answer questions and perform countless other tasks without being trained specifically for any one of them.
That doesn’t diminish the role of specialized AI. It highlights that the two approaches are solving different problems. Increasingly, organizations don’t have to choose between them. Hybrid systems combine the broad reasoning capabilities of foundation models with specialized models trained to execute well-defined tasks with greater precision. Each contributes where it performs best.
For computer vision applied to physical environments, those differences become clear. Aerial imagery, infrastructure inspection and property assessment all depend on identifying subtle visual signals that require deep domain knowledge. Roof material textures, structural damage patterns, seasonal vegetation changes and construction activity over time are fundamentally different from the kinds of visual relationships learned from broad internet-scale datasets.
A model trained on petabytes of diverse internet imagery will recognize a building. A model trained specifically on high-resolution aerial captures of buildings, validated against expert annotations across diverse geographies, will tell you its condition, age class and whether it changed since the last survey.
The investment in understanding a problem domain, crafting definitions, conducting expert labelling and designing custom machine learning models cannot be bypassed simply by prompt engineering on a generic intelligence.
What Strong Validation Looks Like
Validation methodology matters just as much as training data. Academic and commercial AI research has relied heavily on public benchmark datasets for years, but that dependence introduces its own challenges. As benchmark datasets become widely adopted, models naturally become optimized to perform well against those specific tests. High benchmark scores don’t necessarily translate into strong performance under real operating conditions.
Organizations evaluating AI systems should examine how those results were produced. Does the validation data reflect the environment where the model will actually operate? Were the examples representative of real-world conditions? Has the model been tested on data it has never encountered before?
In computer vision, those questions become especially important. Measuring whether a model can identify an object in an image is only one part of the problem. In production, correctness is defined by what is physically present on the ground, regardless of image quality, capture angle, lighting conditions or seasonal variation. A model that performs well under ideal conditions may produce very different results once deployed at scale.
As AI adoption continues to accelerate, organizations will need to become more discerning consumers of performance claims. The benchmark itself deserves as much scrutiny as the reported score. Ultimately, confidence in an AI system comes not from how it performs on a familiar dataset, but from how consistently it performs in the environment where it will be used.
Choosing the Right Architecture
The questions organizations should ask when evaluating AI systems are specific.
How was the model benchmarked, and on what data? Were the test environments representative of real operating conditions, including geographic variation and edge cases? How does performance vary across different asset types or environmental contexts? Can performance claims be independently verified?
Validation shouldn’t end once a model is deployed. Organizations should understand how frequently models are re-evaluated, what triggers retraining, how model versions are managed and what support is provided as systems evolve.
These questions matter because performance gaps tend to surface after deployment, not before. A model that performs well under ideal conditions, or on a few cherry-picked examples, can struggle significantly when it encounters the variability of production environments — different geographies, seasonal changes, data quality inconsistencies, rare but consequential edge cases.
Benchmarking research has documented how models can appear to perform strongly on established benchmarks through data memorization, only to fail on out-of-distribution inputs. The enterprise equivalent is a model that performs impressively in a controlled demonstration and underperforms quietly in production.
These distinctions are already shaping industries such as insurance, infrastructure and government, where even small differences in model performance can carry operational and financial consequences. Continuous post-deployment validation isn’t optional for high-stakes applications; it’s the mechanism through which trust is built.
Organizations should look for transparency around where models perform well and where limitations exist. That openness is evidence that those responsible for the system understand its capabilities and its edges.
The Conversation Shouldn’t be About Which Type of AI “Wins”
General-purpose models excel at language, reasoning, document processing and other tasks involving unstructured information. Specialized AI solves a different class of problems, where precision, repeatability and measurable performance matter most. Both are complementary layers in a mature AI stack.
The organizations that get the most from AI won’t assume the newest or largest model is the right solution for every task. They’ll treat model selection as an engineering decision, evaluating systems against the specific problem they’re trying to solve and demanding evidence that performance holds up outside controlled benchmarks.
From there, the architecture becomes relatively straightforward. First, traditional software for deterministic processes. Second, specialized AI for well-defined prediction problems where accuracy and consistency can be validated, but edge cases are difficult to capture through logical rules alone.
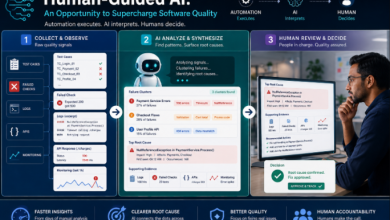
For everything else? Automated, general-purpose AI agents guided and managed by the humans who safeguard what truly matters to the organization.