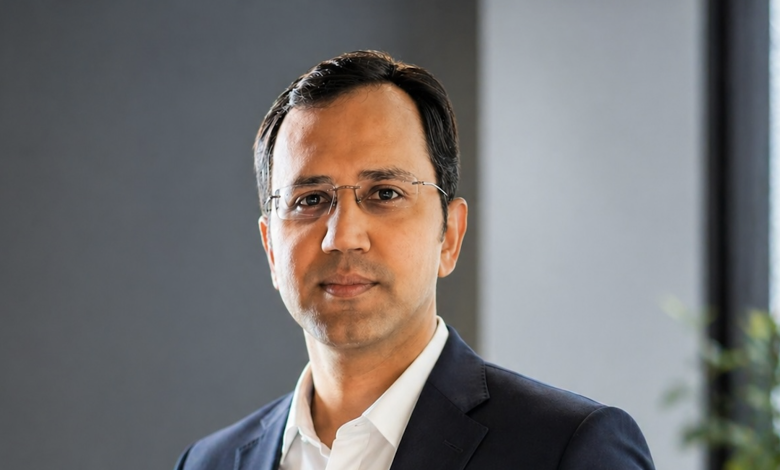
Baber Javed has spent fifteen years building software, and the last several building AI systems where a confident wrong answer has a cost. He is the founding AI engineer at a US platform that uses AI to match students with colleges, where he designed the agentic architecture, the retrieval pipeline and the evaluation framework behind its recommendations. Before that, he built AI for an Australian payroll platform, a domain where the model is never allowed to be the source of truth.
He is also the founder of Square63, the software engineering firm he started in Lahore in 2011 and grew to more than 70 engineers serving clients in the US, UK and Australia, before rebuilding it as a small remote team of senior developers after 2020. That combination of running a firm and writing the code himself gives him a view of AI adoption from both sides of the contract.
His work centers on a specific problem: how to give a language model enough room to be useful while keeping it away from the decisions it shouldn’t own. In this conversation, he walks through the architecture he uses to draw that line, a production failure that looked like personalization until it wasn’t, the eval thresholds his team ships against, and what he’d want a product team to settle before adding an agent to anything.
Why is college counseling a good problem for AI to take on?
Generally, the ratio of available college counselors to students who need guidance is extremely low. There are normally one or two counselors who need to work with hundreds of students, familiarise themselves with the unique profile of each student and give them personalized advice on which colleges they should apply to.
It is very time-consuming and difficult for counselors to have one-on-one meetings with each and every student, gathering context and details about their achievements, goals and what they are aiming for. This would require hundreds of hours and extensive note-taking to build a complete profile for each student and then provide recommendations based on that.
An AI college counselor automates all of the time taking components and tries to reach students where they actually are. A student who doesn’t reply to emails or open a portal, will reply to a text message or attend voice calls. That doesn’t mean counselors get replaced, instead they get a dashboard and access to a system that helps them collect all the information from students in a consolidated and automated manner and allows them to review and provide recommendations to those students in a better and effective manner.
Where does the language model stop in your systems, and what takes over when it does? What determines whether a college match comes from the model, from a retrieval step against verified admissions data, or from a hard-coded rule, and how does the architecture keep the model from overriding those boundaries?
The model is allowed to talk to the student, understand the intent and motives of the student through those conversations, but it’s not allowed to decide what’s true about a college. It reads everything we know about the student and emits a small typed object we call a Search Spec, which contains structured information about the subjects they want to study, hard requirements like location, soft requirements like budget and other similar criteria.
Once the Search Spec is ready, the model steps out of the equation. The subjects map to federal program codes through a lookup table, hard requirements become enforced database filters and soft requirements convert into sorting criteria.
The model is then used to select the best-suited programs from a filtered and narrowed-down list of colleges gathered from the Search Spec. This mechanism ensures that the boundaries and hard requirements provided by the students are never ignored and the combination of the deterministic filters and LLM-based sorting allows us to provide grounded and matching recommendations to students.
Tell me about a moment when a demo that looked solid fell apart in production. Was it the model, the tool calls, the orchestration layer, or something further down like state handling across a multi-step agent?
I encountered one particular issue where a failure looked like successful personalisation. A student initially explored computer science as a subject and the model learned that from several conversations. Later, she became interested in Cognitive Science and started mentioning that she wants to focus on this subject only now. But her recommendations kept drifting back to Computer Science.
There wasn’t anything broken here – the model found schools relevant to the conversations and understood her latest messages as well but still kept including Computer Science recommendations along with the other ones.
The problem was that the previous conversations and recommendations had become part of the context the model used to understand her. This created a feedback loop where repeated mentions of Computer Science was treated as stronger evidence of interest, and then recommended even more computer science. The system was slowly treating its own previous output as evidence about the user interest.
The fix was to start tracking the provenance of information entering the student profile. Something that the student said was always prioritised and carried more weight than anything that came from an LLM-generated output.
The lesson I learned: never let a model turn its own previous outputs into facts. Otherwise, personalization can become a feedback loop disguised as intelligence.
Evaluation seems to be the thing most AI teams say they’ll get to later. What does your eval setup look like in practice: what are you scoring, how large is the test set, do you use LLM-as-judge or human graders, and how do you catch regressions when you swap models or change a prompt?
We have two different sets of the data that we need to test and they both need to be treated differently: conversation quality, where results can be subjective, and matching, which can be tested against a known set of data.
For measuring conversation quality we have an LLM-as-judge implementation which scores conversations on a cumulative score of 1 to 10 based upon the following criteria: repetition, closure and hallucinations.
To measure the quality of the LLM-as-Judge, we have a set of real conversations labelled manually by humans. The judge then scores the same set, and a pass requires at least 30 conversations compared, repetition and closure scores within set bounds, and, for hallucination detection, no false negatives and at most two false positives.
The data set should have at least five conversations the human flagged as hallucinations to properly detect and identify any false positives.
The same datasets serve as our regression tests as well. Whenever we change a prompt or switch to a different model, we rerun the labelled sets and compare them against the existing baseline and thresholds we had previously. If the change causes any critical metric to regress, then we identify the root cause and do not ship the change to production until we fully understand why it regressed.
RAG gets pitched as the fix for hallucination. Where has it let you down, and what did you change in chunking, retrieval, or reranking to fix it?
I initially used RAG to match students to colleges and provide them recommendations on what colleges they should apply to based on their profile. I converted the College programs data that I had into vectors and also vectorised the student programs and performed similarity searches between them. The assumption was that the college vectors closest to the student profile vector would be a good fit however upon deeper analysis we realised that our pipeline hallucinates relevance. It returns something that sounds plausible but in actuality it isn’t. For example it fetches college programs titled History when the student is interested in archaeology only.
Four changes fixed it:
The first was to filter during retrieval rather than afterwards. One of our biggest mistakes was retrieving the most similar results first using vector search and applying hard constraints later, which meant a lot of relevant results were missed in the initial search. We moved filtering into the vector search itself, since most vector databases now allow that.
The second was simplifying ranking. We had built multiple ranking and diversity passes to make sure the final results were relevant without being repetitive, then realised most of that logic could be handled directly by the database using filtering and grouping. A fairly complicated ranking pipeline became a much smaller scoring function.
The third was fixing search starvation. Hard filters solve one problem and create another: a student can specify constraints tight enough that the initial results are very few. We added relevance thresholds and fallback searches that broaden the query when the first pass doesn’t return enough.
The fourth was treating LLM extraction as evidence only. We were using an LLM to turn student conversations into structured preferences, and most of the time the model was reasonable, but sometimes it was too eager to infer intent. Someone mentioning that they enjoy a particular class, activity or environment doesn’t necessarily mean they want to pursue it as a field. We started requiring extracted preferences to be supported by the student’s own words, with normalisation before lookup.
The broader lesson was that improving the system didn’t require a smarter model. Most of the improvements resulted from making retrieval more precise, removing unnecessary ranking logic, handling edge cases explicitly and being much stricter about what we allowed the model to infer.
You built AI for payroll before admissions. Compare the two: what carries over between domains where errors are costly, and what doesn’t? I’m curious whether the guardrails you needed for numerical accuracy translate to something as subjective as a college recommendation.
The architecture is the main thing that gets carried over. On the Payroll project I learned that the LLM cannot be the source of truth as the calculations need to run through deterministic rules and the model is supposed to shortlist the rules and explain the reasoning only. A similar pattern had to be followed in the AI college counselling project where certain facts associated with the college recommendation needed to come from structured data like program names, admission rates and tution fees etc.
Meanwhile, the definition of a correct answer is quite different and subjective in both cases. In payroll there is a correct answer and that can be verified by writing a test for it, However in College matching there is no absolute right or wrong recommendations and there’s no test that can tell us if a school is the right fit for a student.
The consequences of failure are also different. A payroll error is immediate and visible, because someone might get underpaid. A wrong college recommendation is harder to see and shows up much later, if at all, which is exactly what makes evaluation the harder problem in the subjective domain.
Square63 went from 70 engineers to a handful working remotely. Walk me through how that changed the way you run a team, and whether generative AI has widened what a small firm can take on.
With a larger team my job was mostly coordinating and managing people and just keeping a bird’s eye view on the projects. I was mostly managing a system that worked with defined processes and didn’t have to delve into finer technical details. Now with a smaller handful team of senior people, the way of execution is quite the opposite. I’m mostly hands on with writing and analysing code and solutions to a problem and I hire for people who can take a problem and turn it into a production ready solution.
GenAI was widened the breadth of what we can take on. A few years ago, a project that needed Voice, infrastructure and a data pipeline meant we need to hire several engineers to tackle each part of the project. Now one strong engineer equipped with AI tools can cover all of that since majority of the the scaffolding, tests, migrations and boilerplate code gets generated from LLMs.
What AI didn’t change is the responsibility for owning and verifying the systems we develop. Someone still has to decide if the generate code handles all scenarios and is written according in a robust and modular way. Our bottleneck is now reviewing the code we generate and not writing it. So how much more can we deliver now depends upon how much code can we verify and consider safe to be pushed to production.
If a product team told you they were adding an AI agent to an existing product next quarter, what would you want them figured out before writing any code? I’m thinking about things like which actions the agent is allowed to take autonomously, how failures surface to users, and what gets logged for review.
I think I would suggest them think about the outputs the AI agent has to produce and the boudaries it should operate within. The team should really be sure what kind of output the agent should produce which will help them with evaluation of the agent’s behaviour later on. They also need to think about the boundaries of the agent like which actions the agent can take on it’s own, which ones should go through a human and what kind of access level and permissions the agent can have. Every use case is different and the agent should be designed accordingly. Generating a product recommendation or a summary of a meeting is very different from generating a refund request or changing payroll data.
The next should to design is the failure behaviour of the agent. Agents will sometimes misunderstand requests which can end up in invalid tool calls or fetching incorrect data. We should consider that happening and plan for what should happen next – does the agent retry, askl for clarification, fall back to a deterministic rule or escalate to a human?
Another thing I’d emphasize on is Observability. We should be able to reconstruct what happened in each of our LLM calls. What the user asked, what context the agent had, which tools it called, what those tools returned, what decision it made, and what action was ultimately taken. Without all of this information, debugging an agent becomes guesswork.
Once those things are clear, choosing the model, framework, prompts, and orchestration architecture becomes much easier. The hard part of building an agent is rarely getting it to do something. It’s deciding what it should be trusted to do when nobody is testing and analysing it in production.